Conceptual Foundation & Intuitive Analogy
🧭 Conceptual Foundation & Pattern Intuition
Dynamic Programming (DP) is the algorithmic realization of mathematical induction: solving a complex problem by breaking it down into overlapping subproblems and storing subproblem answers to avoid exponential recomputation. A problem exhibits optimal substructure if an optimal solution to the problem contains optimal solutions to its subproblems. In Climbing Stairs, to reach step , you must have taken either a 1-step leap from step or a 2-step leap from step . Therefore, the total distinct ways to reach step is simply the sum: .
🏟️ The Analogy: The Staircase of Milestones
Imagine standing in front of a flight of stairs. You can take either 1 step or 2 steps at a time.
- Step 1 has only 1 way (take 1 step).
- Step 2 has 2 ways (1+1 or a single 2-step jump).
- What about Step 3? To land on Step 3, you must have been on Step 2 (and took 1 step) OR on Step 1 (and took 2 steps). There are no other physical possibilities! So total ways to Step 3 =
ways(2) + ways(1) = 2 + 1 = 3. - What about Step 4? It is simply
ways(3) + ways(2) = 3 + 2 = 5.
You never need to recount steps from the ground floor; you simply add the two numbers written on the steps beneath your feet!
🔑 Why It Works
Notice how the recurrence only looks back 2 steps. We don't need an array of size ; two scalar variables (prev1, prev2) act as a sliding register, collapsing an space table into constant memory!
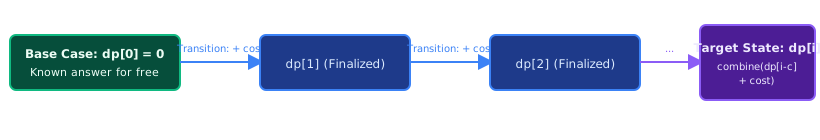
When I compute dp[i], every smaller state it depends on is already final and correct. The loop order is what guarantees that.
Optimal substructure: DP state dp[i] depends strictly on already-computed subproblems. Rolling array reduces space from O(S) to O(1 tier).
Iterate base cases -> compute states in topological transition order (dp[i] = min/max/sum of transitions).
The 11 Mental Models of Dynamic Programming
Identify the state signature and transition dependency direction before allocating tables.
1Memoization
brute-force recursion ➔ cache results by arguments ➔ each state solved onceMemoized Recursion (Top-Down DP, Memo DFS): a technique for any state shape
| 1 | from typing import Callable, Dict, Hashable, TypeVar |
| 2 | |
| 3 | R = TypeVar("R") |
| 4 | |
| 5 | |
| 6 | def memoize(recurrence: Callable[[Hashable, Callable[[Hashable], R]], R]) -> Callable[[Hashable], R]: |
| 7 | """Memoization: solve(state) with each state's answer computed once and then looked up. |
| 8 | recurrence(state, solve) computes the answer for state, calling solve on smaller states. |
| 9 | Precondition: the answer depends only on state, and the calls never loop back to a state in progress. |
| 10 | S = distinct states. T = the cost of one recurrence call besides the solve calls it makes. |
| 11 | Time: O(S * T) | Space: O(S) memo and recursion stack |
| 12 | """ |
| 13 | # memo: memo[state] holds the finished answer for state, once it has been computed |
| 14 | memo: Dict[Hashable, R] = {} |
| 15 | |
| 16 | def solve(state: Hashable) -> R: |
| 17 | # 1. Compute Once, Then Reuse: |
| 18 | # The first call for a state runs the recurrence and stores the answer before returning, so |
| 19 | # every later call for the same state is a lookup instead of a repeated exploration. |
| 20 | if state not in memo: |
| 21 | memo[state] = recurrence(state, solve) |
| 22 | return memo[state] |
| 23 | |
| 24 | return solve |
The number of ways to decode s[index:] depends only on index, never on how the digits before it were split, so dfs(index) stores its answer in memo[index] the first time it finishes and returns that stored value on every later call. The plain recursion reaches the same index along many different split paths; with the memo, each index explores its one-digit and two-digit branches only once, and every repeated call is a lookup that returns exactly what exploring again would have returned. The trap is the key: memo must be keyed by every argument that changes the answer. Here that is index alone, but in Interleaving String (LC 97) the answer depends on how far both strings are used, so the key is (i, j); key by i alone and a call that has used 2 letters of s2 gets the answer stored for one that used 5.
Gotcha 1 of 5
- The trap
Gotcha 1: Keying
memobyiwhen the answer depends on(i, j)Mistakememo[i] = resFixmemo[(i, j)] = resWhat happens:
memomust be keyed by every argument that changes the answer. In Decode Ways (LC 91), that isindexalone. In Interleaving String (LC 97),dfs(i, j)depends on bothiandj. With the keyi, a call gets the answer stored for a differentj.Example: Interleaving String (LC 97): s1 = "a", s2 = "ab", s3 = "aba"Mistake: returns FalseFix: returns True
2Linear DP
dp[i] = the answer for the first i steps ➔ built from dp[i-1] and dp[i-2] ➔ O(1) rolling registers1D DP (Linear DP)
i is built only from the answers at the last one or two positions: steps of 1 or 2, counts of ways, best totals.| 1 | from typing import Callable |
| 2 | |
| 3 | |
| 4 | def linear_dp(n: int, first_two: tuple[int, int], combine: Callable[[int, int, int], int]) -> int: |
| 5 | """Linear DP: dp[i] is built from dp[i - 1] and dp[i - 2], kept in two rolling variables. |
| 6 | combine(prev1, prev2, i) returns dp[i] from the two answers before it. |
| 7 | Precondition: first_two is (dp[0], dp[1]) and n >= 1. |
| 8 | T = the time of one combine call. |
| 9 | Time: O(N * T) | Space: O(1) |
| 10 | """ |
| 11 | # prev2, prev1: dp[i - 2] and dp[i - 1], the only two answers the next one needs |
| 12 | prev2, prev1 = first_two |
| 13 | for i in range(2, n + 1): |
| 14 | # 1. Build dp[i] From The Last Two Answers: |
| 15 | # Both answers are final, so one call to combine gives dp[i] without looking further back. |
| 16 | curr = combine(prev1, prev2, i) |
| 17 | |
| 18 | # 2. Roll The Window Forward: |
| 19 | # prev2 takes the old prev1 first, because prev1 is overwritten on the next line. |
| 20 | prev2 = prev1 |
| 21 | prev1 = curr |
| 22 | |
| 23 | return prev1 |
dp[i] depends only on dp[i - 1] and dp[i - 2], so keep just those two answers in prev1 and prev2 and move them forward once per step, instead of storing a table. Decide what dp[i] means before writing the formula. Each dp[i] is built from two answers that are already final, so every answer is computed once, in order, and dp[n] is complete when the loop ends. The trap is the shift: set prev2 = prev1 before prev1 = curr, or prev2 is overwritten by the new value and both variables hold the same answer.
Gotcha 1 of 3
- The trap
Gotcha 1: Setting
prev1 = currbeforeprev2 = prev1Mistakeprev1 = curr prev2 = prev1Fixprev2 = prev1 prev1 = currWhat happens:
prev1holdsdp[i - 1]andprev2holdsdp[i - 2]. The nextdp[i - 2]is the oldprev1. Ifprev1 = currruns first, that old value is lost. Thenprev2 = prev1copiescurr, so both variables hold the same value.Example: Climbing Stairs (LC 70): n = 5Mistake: returns 16Fix: returns 8
3Unbounded Knapsack
items & capacities ➔ capacity loop runs upward so an item can repeat ➔ dp[w]Unbounded Knapsack (Coin Change, Coin Change II)
| 1 | def coin_change(coins: list[int], amount: int) -> int: |
| 2 | """Unbounded Knapsack: the fewest coins that make amount, each coin usable any number of times (forward loop). |
| 3 | Time: O(N * amount) | Space: O(amount) |
| 4 | """ |
| 5 | # dp: dp[w] is the fewest coins that make amount w; infinity marks w as not yet reachable |
| 6 | dp = [float('inf')] * (amount + 1) |
| 7 | dp[0] = 0 |
| 8 | for coin in coins: |
| 9 | for w in range(coin, amount + 1): |
| 10 | # 1. Reuse This Coin Forward: |
| 11 | # The forward loop lets dp[w - coin] already include this coin, so one coin may be used any number of times. |
| 12 | dp[w] = min(dp[w], dp[w - coin] + 1) |
| 13 | return int(dp[amount]) if dp[amount] != float('inf') else -1 |
Treat each amount as its own subproblem: dp[w] is the fewest coins that make w, and each coin updates it from dp[w - coin]. Loop w upward, so dp[w - coin] may already include this coin and the coin can repeat. Start from infinity, which marks an amount as not yet reachable, and only dp[0] = 0. The trap is the loop direction: for w in range(coin, amount + 1), not downward, which would use each coin at most once.
Gotcha 1 of 3
- The trap
Gotcha 1: Looping
wdownward when items can be reusedMistakefor w in range(amount, coin - 1, -1):Fixfor w in range(coin, amount + 1):What happens: Going upward,
dp[w - coin]may already include thiscoin, sodp[w]can use it again. That is what 'any number of times' needs. Going downward readsdp[w - coin]before this pass updates it, so each coin is used at most once, which is the 0/1 rule. Withcoins = [2], amount 4 needs the coin twice.Example: coins = [2], amount = 4Mistake: returns -1Fix: returns 2
4Grid DP
grid dp[i][j] ➔ depends on the cell above and the cell to the left ➔ 1D rolling row2D DP: Grid Paths (Unique Paths, Minimum Path Sum)
| 1 | def unique_paths(m: int, n: int) -> int: |
| 2 | """Unique Paths: count right/down paths in an m x n grid with one rolling row. |
| 3 | Time: O(M * N) | Space: O(N) |
| 4 | """ |
| 5 | # row: one rolling row of the DP grid; row[j] starts at 1 since row 0 is reached only by moving right |
| 6 | row = [1] * n |
| 7 | for _ in range(1, m): |
| 8 | for j in range(1, n): |
| 9 | # 1. Combine Above And Left: |
| 10 | # row[j] still holds the count from the row above; add row[j - 1], already updated for this row. |
| 11 | row[j] += row[j - 1] |
| 12 | return row[n - 1] |
Give every grid cell (i, j) one answer, and build it only from the cell above and the cell to its left. Fill the grid row by row, so both cells are already final, and keep just one rolling row: row[j] still holds the answer from above when you add row[j - 1], the answer from the left. The trap is the first column: row[0] has no left neighbour and stays 1, so the inner loop must start at j = 1; starting at 0 reads row[-1], the last cell.
Gotcha 1 of 3
- The trap
Gotcha 1: Starting
jat 0 inunique_pathsMistakefor j in range(0, n):Fixfor j in range(1, n):What happens: Column 0 is reached in exactly one way, so
row[0]must stay 1. Withj = 0, the line readsrow[-1], which is the last cell. Python raises no error. On one column,row[0] += row[0]doubles the cell on every row.Example: m = 5, n = 1Mistake: returns 16Fix: returns 1
50/1 Knapsack
items & capacities ➔ capacity loop runs downward so each item counts once ➔ dp[w]0/1 Knapsack (Partition Equal Subset Sum, Subset Sum)
| 1 | def can_partition(nums: list[int]) -> bool: |
| 2 | """0/1 Knapsack: Partition array into two equal subsets (reverse loop). |
| 3 | Time: O(N * Target) | Space: O(Target) |
| 4 | """ |
| 5 | total = sum(nums) |
| 6 | if total % 2 != 0: |
| 7 | return False |
| 8 | target = total // 2 |
| 9 | # dp: dp[w] is True when sum w is reachable using only the items processed so far |
| 10 | dp = [False] * (target + 1) |
| 11 | dp[0] = True |
| 12 | for x in nums: |
| 13 | for w in range(target, x - 1, -1): |
| 14 | # 1. Use This Item At Most Once: |
| 15 | # The reverse loop reads dp[w - x] before this pass updates it, so x is counted at most once per w. |
| 16 | dp[w] = dp[w] or dp[w - x] |
| 17 | return dp[target] |
Treat each sum as its own subproblem: dp[w] is True when the items seen so far can add up to w, and each item x updates it from dp[w - x]. Loop w downward, so dp[w - x] has not been touched by the current x yet and x is counted at most once; looping upward would let the same x fill dp[w - x] and then dp[w] in one pass. The trap is exactly that loop direction: for w in range(target, x - 1, -1), not range(x, target + 1).
Gotcha 1 of 3
- The trap
Gotcha 1: Looping
wupward in a 0/1 problemMistakefor w in range(x, target + 1):Fixfor w in range(target, x - 1, -1):What happens: Going upward,
dp[w - x]may already include the currentx. Thendp[w]usesxa second time. Herex = 1makes every sum from 1 to 4 reachable, so the target 4 looks reachable. Going downward,dp[w - x]still describes only the items beforex.Example: nums = [1, 2, 5]Mistake: returns TrueFix: returns False
6LIS
array ➔ tails array maintenance ➔ binary search replacementLongest Increasing Subsequence (Patience Sorting)
| 1 | import bisect |
| 2 | |
| 3 | def length_of_lis(nums: list[int]) -> int: |
| 4 | """Longest Increasing Subsequence via Patience Sorting. |
| 5 | Time: O(N log N) | Space: O(N) |
| 6 | """ |
| 7 | # tails: sorted; tails[k] is the smallest last value of any increasing subsequence of length k + 1 seen so far |
| 8 | tails: list[int] = [] |
| 9 | |
| 10 | for x in nums: |
| 11 | # 1. Find Where x Fits: |
| 12 | # bisect_left finds the first tail >= x, the pile x can legally extend or replace. |
| 13 | idx = bisect.bisect_left(tails, x) |
| 14 | if idx == len(tails): |
| 15 | # 2. Start A Longer Subsequence: |
| 16 | # No tail is >= x, so x extends the longest subsequence found so far by one. |
| 17 | tails.append(x) |
| 18 | else: |
| 19 | # 3. Lower An Existing Tail: |
| 20 | # x is smaller than tails[idx], so it leaves more room for later values at this same length. |
| 21 | tails[idx] = x |
| 22 | |
| 23 | return len(tails) |
Keep tails[k] as the smallest last value of any increasing subsequence of length k + 1, and for each x replace the first tail that is >= x (found with bisect_left), or append x when there is none. A smaller tail can only help, because it leaves more room for the values that come later, and replacing never breaks the order of tails, so len(tails) is always the longest length reached so far. The trap is reading tails as the answer: it has the right length but is usually not a real subsequence, so store each element's predecessor index when you must rebuild the sequence.
Gotcha 1 of 3
- The trap
Gotcha 1: Returning
tailsas the subsequenceMistakereturn tailsFixreturn len(tails)What happens:
tails[k]is the smallest last value of any increasing subsequence of lengthk + 1. Its length is right. Its values can come from different subsequences, in the wrong order. To rebuild a real subsequence, store each element's predecessor index.Example: nums = [3, 4, 1]Mistake: returns [1, 4]Fix: returns 2
7State Machine DP
states (hold, sold, rest) ➔ day-by-day transitions ➔ best final stateState Machine DP (Buy/Sell Stock)
| 1 | def max_profit(prices: list[int]) -> int: |
| 2 | """Best Time to Buy and Sell Stock II: 2-state machine, unlimited transactions. |
| 3 | States: hold (own one share), cash (own no share) |
| 4 | Time: O(N) | Space: O(1) |
| 5 | """ |
| 6 | # hold, cash: best profit so far while owning one share (hold) or owning none (cash) |
| 7 | hold = -prices[0] |
| 8 | cash = 0 |
| 9 | |
| 10 | for i in range(1, len(prices)): |
| 11 | p = prices[i] |
| 12 | # 1. Transition Both States From Yesterday: |
| 13 | # hold keeps the share or buys today (cash - p); cash stays out or sells today (hold + p). |
| 14 | # Both right-hand sides read yesterday's hold and cash, before either is overwritten. |
| 15 | hold, cash = max(hold, cash - p), max(cash, hold + p) |
| 16 | |
| 17 | # Ending while still holding a share is never better than ending with it sold. |
| 18 | return cash |
At the end of each day you are in exactly one of two states, owning a share (hold) or not (cash), and each state's best profit follows only from yesterday's two values: hold = max(hold, cash - p) keeps the share or buys today, and cash = max(cash, hold + p) stays out or sells today. Every legal run of buys and sells is a path through these states and each line keeps only the best way to arrive, so the last cash is the best profit of all; a cooldown, a fee or a trade limit just adds a state or a term, as long as every update reads yesterday's values. The trap is the start: hold = -prices[0], not 0, because hold = 0 means owning a share you never paid for, and selling it would add its full price to cash as profit.
Gotcha 1 of 4
- The trap
Gotcha 1: Starting with
hold = 0instead ofhold = -prices[0]Mistakehold = 0Fixhold = -prices[0]What happens:
holdis the best profit while owning one share.hold = 0means owning a share that cost nothing. Selling it adds its full price tocashas profit. Buying on day 0 costsprices[0], sohold = -prices[0].Example: prices = [5, 3]Mistake: returns 3Fix: returns 0
8Interval DP
range dp[i][j] ➔ built from shorter ranges inside it ➔ fill by increasing lengthInterval DP (Longest Palindromic Subsequence)
| 1 | def longest_palindrome_subseq(s: str) -> int: |
| 2 | """Longest Palindromic Subsequence: interval DP over the range s[i..j], filled from short ranges to long ones. |
| 3 | Time: O(N^2) | Space: O(N^2) |
| 4 | """ |
| 5 | n = len(s) |
| 6 | # dp: dp[i][j] is the length of the longest palindromic subsequence of s[i..j]; one letter is a palindrome of length 1 |
| 7 | dp = [[0] * n for _ in range(n)] |
| 8 | for i in range(n): |
| 9 | dp[i][i] = 1 |
| 10 | |
| 11 | # 1. Fill By Increasing Range Length: |
| 12 | # dp[i][j] reads dp[i + 1][j - 1], dp[i + 1][j] and dp[i][j - 1], all shorter ranges, so they must be final first. |
| 13 | for length in range(2, n + 1): |
| 14 | for i in range(n - length + 1): |
| 15 | j = i + length - 1 |
| 16 | # 2. Match The Two Ends, Or Drop One: |
| 17 | # Equal end letters wrap the answer for the inside range with 2 more; otherwise one end cannot be used, so drop it. |
| 18 | if s[i] == s[j]: |
| 19 | dp[i][j] = dp[i + 1][j - 1] + 2 |
| 20 | else: |
| 21 | dp[i][j] = max(dp[i + 1][j], dp[i][j - 1]) |
| 22 | |
| 23 | return dp[0][n - 1] |
Give every range s[i..j] one answer, dp[i][j], and build it only from shorter ranges inside it: when the two end letters match, they wrap the answer for the inside range dp[i + 1][j - 1] with 2 more; when they differ, one of them cannot be used, so take the better of dropping the left end (dp[i + 1][j]) or the right end (dp[i][j - 1]). Every shorter range is final before it is read, because the table is filled by increasing range length. The trap is the fill order: looping i upward row by row reads dp[i + 1][j - 1] while it is still 0, so fill by length, short ranges first.
Gotcha 1 of 3
- The trap
Gotcha 1: Filling
dprow by row fromi = 0Mistakefor i in range(n): for j in range(i + 1, n):Fixfor length in range(2, n + 1): for i in range(n - length + 1): j = i + length - 1What happens:
dp[i][j]readsdp[i + 1][j - 1]anddp[i + 1][j], which belong to rows further down the table. A loop that runsiupward from 0 reads those cells while they are still 0, so the answer is too small. Fill bylength, short ranges first, or runifromn - 1down to 0.Example: s = "bbbab"Mistake: returns 2Fix: returns 4
9Probability DP
state probability dp[s] ➔ spread over the equally likely moves each step ➔ total on the states that countProbability DP (Knight Probability, New 21 Game)
| 1 | def knight_probability(n: int, k: int, row: int, column: int) -> float: |
| 2 | """Probability DP: spread each square's probability over the 8 knight moves, k times, and total what stays on the board. |
| 3 | Time: O(K * N^2) | Space: O(N^2) |
| 4 | """ |
| 5 | moves = [(1, 2), (2, 1), (2, -1), (1, -2), (-1, -2), (-2, -1), (-2, 1), (-1, 2)] |
| 6 | # dp: dp[r][c] is the probability that the knight stands on (r, c) after the moves made so far, never having left the board |
| 7 | dp = [[0.0] * n for _ in range(n)] |
| 8 | dp[row][column] = 1.0 |
| 9 | |
| 10 | for _ in range(k): |
| 11 | nxt = [[0.0] * n for _ in range(n)] |
| 12 | for r in range(n): |
| 13 | for c in range(n): |
| 14 | # 1. Spread Each Square's Probability Over The 8 Moves: |
| 15 | # Each move has chance 1/8, so a square passes dp[r][c] / 8 to every target that is still on the board. |
| 16 | for dr, dc in moves: |
| 17 | nr, nc = r + dr, c + dc |
| 18 | if 0 <= nr < n and 0 <= nc < n: |
| 19 | nxt[nr][nc] += dp[r][c] / 8 |
| 20 | # 2. Replace The Board With The New Step: |
| 21 | # The share that fell off the board is added nowhere, so it is gone for every later step. |
| 22 | dp = nxt |
| 23 | |
| 24 | # 3. Add Up What Is Left On The Board: |
| 25 | # Each square holds the probability of being there after k moves without leaving, so their total is the answer. |
| 26 | return sum(sum(line) for line in dp) |
Give every state the probability of being there after the steps made so far, and build the next step by passing each state's share to the states it can move to: with 8 equally likely moves, a square passes dp[r][c] / 8 to each target. A target off the board adds nothing, so that share is lost for good. Build the new step in a fresh board nxt and replace dp after the pass, so a share is never passed on twice in one step. The trap is the chance of each move: pass dp[r][c] / 8, not dp[r][c], or the table counts paths and the answer is far above 1.
Gotcha 1 of 3
- The trap
Gotcha 1: Passing the whole probability instead of one eighth
Mistakenxt[nr][nc] += dp[r][c]Fixnxt[nr][nc] += dp[r][c] / 8What happens: A knight picks one of its 8 moves with equal chance, so each target receives one eighth of the square's probability. Without the division, each target receives the whole probability. The table then counts paths, and the answer is far above 1.
Example: n = 3, k = 2, row = 0, column = 0Mistake: returns 4.0Fix: returns 0.0625
10Bitmask DP
about 20 items ➔ bitmask of used items ➔ dp[mask]Bitmask DP (Shortest Path Visiting All Nodes, TSP)
| 1 | def minimum_xor_sum(nums1: list[int], nums2: list[int]) -> int: |
| 2 | """Minimum XOR Sum of Two Arrays: bitmask DP over which numbers of nums2 are already paired. |
| 3 | Time: O(N * 2^N) | Space: O(2^N) |
| 4 | """ |
| 5 | n = len(nums2) |
| 6 | # dp: dp[mask] is the least XOR sum pairing the first popcount(mask) numbers of nums1 with the nums2 set in mask |
| 7 | dp = [float("inf")] * (1 << n) |
| 8 | dp[0] = 0 |
| 9 | |
| 10 | for mask in range(1 << n): |
| 11 | # 1. Find The Next nums1 Index From The Mask: |
| 12 | # The count of set bits is how many nums1 numbers are already paired, so the next one is nums1[i]. |
| 13 | i = bin(mask).count("1") |
| 14 | if i == n: |
| 15 | continue |
| 16 | for j in range(n): |
| 17 | if not mask & (1 << j): |
| 18 | # 2. Pair nums1[i] With A Free nums2[j]: |
| 19 | # mask | (1 << j) is always larger than mask, so this same upward loop reaches it later |
| 20 | # with dp[mask] already final; keep the smaller total found for that larger state. |
| 21 | nxt = mask | (1 << j) |
| 22 | dp[nxt] = min(dp[nxt], dp[mask] + (nums1[i] ^ nums2[j])) |
| 23 | |
| 24 | return dp[(1 << n) - 1] |
When n is small, keep one best answer per set of used items and write the set as the bits of an integer: dp[mask] is the least XOR sum after pairing the first i numbers of nums1 with the nums2 numbers whose bits are set in mask, where i = bin(mask).count("1"). From each mask, pair nums1[i] with every free nums2[j] (not mask & (1 << j)) and keep the smaller total in dp[mask | (1 << j)]. This is correct because the rest of the pairing depends only on which nums2 numbers are used, not on the order they were used in, so the n! orders collapse into 2^n states; and mask | (1 << j) is always larger than mask, so an upward loop over mask finishes every state before it is read. The trap is tracking the nums1 index yourself: pairing any nums1[i] with the mask does not record which nums1 numbers are already used, so one can be paired twice. i must come from the mask.
Gotcha 1 of 5
- The trap
Gotcha 1: Looping over every
iinstead ofi = bin(mask).count("1")Mistakefor i in range(n):Fixi = bin(mask).count("1")What happens:
maskrecords whichnums2numbers are used. It does not record whichnums1numbers are used. The count of set bits is how manynums1numbers are paired, so the next one isnums1[i]. A loop over everyican pair the samenums1number again and again.Example: nums1 = [2, 4, 8], nums2 = [1, 1, 1]Mistake: returns 9Fix: returns 17
11Digit DP
limit n ➔ fill digits left to right with a tight flag ➔ countDigit DP
n (up to 10^9 or more) share some digit property: how many contain a 1, how many can be written from a given digit set, how many have no repeated digit. Checking each number one by one is far too slow.| 1 | from functools import lru_cache |
| 2 | |
| 3 | def count_digit_one(n: int) -> int: |
| 4 | """Number of Digit One: digit DP over the digits of n, keeping whether the prefix still equals n's. |
| 5 | Time: O(D^2 * 10) | Space: O(D^2) |
| 6 | """ |
| 7 | # digits: n's digits, most significant first; size is how many digit positions the walk fills |
| 8 | digits = [int(c) for c in str(n)] |
| 9 | size = len(digits) |
| 10 | |
| 11 | @lru_cache(maxsize=None) |
| 12 | def count(pos: int, ones: int, tight: bool) -> int: |
| 13 | """The 1s in every number that finishes this prefix, which already holds `ones` 1s.""" |
| 14 | # 1. Finish A Number: |
| 15 | # Every digit is placed; the finished number contributes the 1 digits it already holds. |
| 16 | if pos == size: |
| 17 | return ones |
| 18 | # 2. Cap This Digit While Tight: |
| 19 | # tight means the prefix still equals n's digits, so this digit may not pass n's digit here. |
| 20 | top = digits[pos] if tight else 9 |
| 21 | total = 0 |
| 22 | for d in range(top + 1): |
| 23 | # 3. Place Digit d And Stay Tight Only On n's Own Digit: |
| 24 | # A digit below top makes every later digit free (0-9), so tight must carry forward only |
| 25 | # when it was already tight and d matches n's digit exactly here. |
| 26 | total += count(pos + 1, ones + (d == 1), tight and d == top) |
| 27 | return total |
| 28 | |
| 29 | return count(0, 0, True) |
Build every number up to n digit by digit, from the most significant digit, and keep one bit of history about the limit: tight, whether the digits placed so far equal n's. While tight, the next digit may not pass n's digit there; once a smaller digit has been placed, every later digit is free from 0 to 9. Add whatever extra fact the question needs to the state, here ones, the count of 1 digits placed so far, and memoize on the whole state: count(pos, ones, tight). This is correct because two prefixes with the same (position, extra fact, tight) finish in exactly the same set of ways, so each state needs solving only once, and the base case at pos == size reads off the answer for a finished number. The trap is the tight bit: the next position stays tight only when tight and d == top, never d == top alone. Dropping the tight and part re-caps a number that is already smaller than n, undercounting it.
Gotcha 1 of 4
- The trap
Gotcha 1: Writing
d == topinstead oftight and d == topMistaketotal += count(pos + 1, ones + (d == 1), d == top)Fixtotal += count(pos + 1, ones + (d == 1), tight and d == top)What happens: Once a digit below
n's digit is placed, the number is already smaller thann. Every later digit is then free from 0 to 9. Withd == topalone, a later 9 setstightto True again. The next digit is then capped atn's digit, and some numbers are never counted.Example: n = 100Mistake: returns 20Fix: returns 21
Built on the mental models above
- Best Sightseeing PairBest Left Half Carry (Best Sightseeing Pair)
The score of a pair splits into one term for the left spot and one term for the right spot, so one carried value,
best_left, is the whole state. - Kadane's AlgorithmKadane's Algorithm (Maximum Subarray)
The state is the best sum of a subarray that ends at
i, and each step either extends it or starts fresh ati. - Maximum Product SubarrayKadane's Algorithm with a Product (Maximum Product Subarray)
A negative number turns the smallest product into the largest, so keep both
hiandlo, the largest and smallest product of a subarray that ends here. - Circular KadaneKadane's Algorithm on a Circular Array (Maximum Sum Circular Subarray)
A run may wrap around the end, and that run is the total minus the worst plain run, so run Kadane a second time with
minand keep the total. - Max Absolute Subarray SumKadane's Algorithm for the Best and the Worst Run (Maximum Absolute Sum of Any Subarray)
The answer is an absolute value, so run Kadane twice, with
maxand withmin, let each run restart at 0, and take the larger ofcurr_maxand-curr_min. - Turbulent SubarrayKadane's Algorithm with a Direction (Longest Turbulent Subarray)
A run grows only when its next step goes the opposite way, so keep one length per direction of the last step,
upanddown, and flip them on each step. - Kadane with One DeletionKadane's Algorithm with One Deletion (Maximum Subarray Sum with One Deletion)
One number may be deleted, so keep a second state,
drop: the best sum ending here with one number deleted. Deletingxtakes the oldkeep. - House RobberHouse Robber (Non-Adjacent Maximum Sum)
Each item is now take or skip, and taking item
irules out itemi - 1, so the recurrence becomesdp[i] = max(dp[i - 1], dp[i - 2] + x). - Two-Sequence DPTwo-Sequence DP (Longest Common Subsequence, Edit Distance)
The two axes of the table are the prefixes of two sequences, and a cell also looks at the cell diagonally up and to the left.
- Distinct SubsequencesDistinct Subsequences Counting DP
It counts the ways one string can be picked out of another, so each cell adds counts instead of taking a best value.
- Last-Char Counting DPLast-Character Counting DP (Distinct Subsequences II)
The mode is the last letter used, with up to 26 modes, and every count is updated together on each character.
- Burst BalloonsBurst Balloons (Choose the Last Item in a Range)
Each range also chooses the last item handled inside it, and that choice splits the range into two independent halves.
- Minimax DPGame Theory / Minimax DP (Stone Game, Predict the Winner)
Two players take turns on one range of items, and each cell keeps the score difference for the player to move.
The Dynamic Programming Decision Rule
When facing an unseen optimization or counting problem, ask in this order:
Keep hi and lo, the largest and smallest product of a subarray that ends at x, and update both from x, hi * x and lo * x.
Run Kadane twice, once with max for the best plain run and once with min for the worst, keep the total, and take the larger of best and total - worst.
Run Kadane twice, with max for the best run and min for the worst run, each restarting at 0, and take the larger of curr_max and -curr_min.
Keep up and down, the longest run ending here whose last step went up or down; a step up extends down, a step down extends up, and an equal step restarts both.
Keep keep and drop, the best run ending here with nothing deleted and with one number deleted; drop = max(keep, drop + x) is computed before keep is updated.
At each number, either extend the best run that ends just before it or start fresh at it: curr = max(x, curr + x), and keep the largest curr.
Regroup the score as (values[i] + i) + (values[j] - j), carry best_left, the largest values[i] + i of the spots before j, and score each j against it before you update best_left with j.
dp[i] = max(dp[i - 1], dp[i - 2] + x): skip the item, or take it on top of the best from two back.
Maintain rolling registers a, b = b, transition(a, b) in O(1) space.
dp[i][j] = dp[i-1][j], plus dp[i-1][j-1] when s[i-1] == t[j-1]; every dp[i][0] = 1.
Keep one running count per last letter, ends[c]; on each character, ends[ch] = sum(ends) + 1, replacing the old ends[ch], never adding to it.
Define dp[i][j] over the prefixes text1[:i] and text2[:j]; a match builds on the diagonal cell, and a mismatch combines the cell above and the cell to the left.
Define dp[i][j] for grid cell (i, j) and combine the cell above and the cell to the left, keeping one rolling row.
Index dp by the capacity and loop it downward for each item, so an item is used at most once.
Index dp by the capacity and loop it upward for each item, so an item may repeat; for counting combinations keep the items in the outer loop.
Maintain tails array with bisect_left in O(N log N); for envelopes, sort by width ascending and height descending first.
Keep one best value per state and update every state from the previous step's values.
dp[i][j] = best over k of dp[i][k] + dp[k][j] + cost(i, k, j), where k is the LAST item handled between i and j; fill shorter intervals first.
Define dp[i][j] for the range i..j, fill by increasing range length, and build each cell from shorter ranges inside it.
dp[state] = best over moves of (gain of the move - dp[next state]): the score difference for the player to move.
Index dp by a bitmask of the used items (plus the last item when it matters) and fill masks in increasing order.
Fill digits left to right, carrying a tight flag (still equal to n's prefix) and the property's state; memoize the states.
Let dp[state] be the probability of being in a state after the steps made so far, pass each state's share to the states it can move to, and total the states that count.
Cache results by the arguments (@cache), so each state is solved once.
Pattern Architecture & Invariant Design Masterclass
Dynamic programming is one observation applied ruthlessly: a big problem's answer is built from smaller versions of the same problem, and the same small versions keep coming up. Compute each small version once, write it down, and look it up thereafter. That is the whole idea. Everything else is bookkeeping.
Two conditions must both hold, and naming them is how you recognise a DP problem rather than guessing:
- Optimal substructure — the best answer to the whole contains the best answers to its parts. The cheapest way to make 11 cents is one coin plus the cheapest way to make (11 − that coin) cents.
- Overlapping subproblems — the same parts are needed over and over. Naive recursion for "make 11 cents" recomputes "make 6 cents" an exponential number of times.
If only condition 1 holds, you have divide and conquer (see dfs.md), not DP — merge sort never solves the same half twice, so there is nothing to cache.
The three questions that turn any DP problem into code, in this exact order:
- What is the state? What is the smallest set of facts that fully describes a sub-question? (Here: "the amount I am trying to make." One number.)
- What is the transition? How is one state's answer built from smaller states' answers? (Here:
dp[i] = min over coins of dp[i − coin] + 1.) - What is the base case? Which state's answer is known without computing anything? (Here:
dp[0] = 0— making zero costs zero coins.)
🔬 Variable Anatomy: The 7 Variables Every DP Solution Uses
To connect abstract dynamic programming recurrences with concrete Python syntax, here is the universal code anatomy showing what every variable does:
def dpMasterTemplate( nums: list[int], target: int, coins: list[int]) -> tuple[int, int, int]: # ========================================================================= # 1. THE STATE TABLES & MEMORY BUFFERS # ========================================================================= # Table sized target + 1; initialized to unreachable sentinel dp = [float('inf')] * (target + 1) # 📊 Tabulation Table: dp[i] = optimal answer for amount i dp[0] = 0 # 🏁 Base State Identity: 0 cost to form 0 amount # Rolling registers for O(1) space optimization (Climbing Stairs / House Robber) prev2, prev1 = 0, 0 # 🔄 Constant-Space Sliding Registers # Patience sorting tails array for O(N log N) LIS tails = [] # 📈 Monotonic Subsequence Thresholds # ========================================================================= # 2. 1D UNBOUNDED KNAPSACK TABULATION (COIN CHANGE) # ========================================================================= for rem in range(1, target + 1): for coin in coins: # Transition Guard: ensure subproblem is non-negative and reachable if rem - coin >= 0 and dp[rem - coin] != float('inf'): # Combine: Bellman optimality principle dp[rem] = min(dp[rem], dp[rem - coin] + 1) min_coins = dp[target] if dp[target] != float('inf') else -1 # ========================================================================= # 3. 1D LINEAR CHOICE TRANSITION (HOUSE ROBBER) # ========================================================================= for x in nums: # dp[i] = max(dp[i-1], dp[i-2] + x) curr = max(prev1, prev2 + x) prev2, prev1 = prev1, curr max_loot = prev1 # ========================================================================= # 4. MONOTONIC PATIENCE SORTING (LIS) # ========================================================================= import bisect for x in nums: idx = bisect.bisect_left(tails, x) if idx == len(tails): tails.append(x) else: tails[idx] = x # Lower threshold for future candidates lis_length = len(tails) return min_coins, max_loot, lis_length Variable Role Reference:
| Variable | Role in Code | Question It Answers | ❌ What Happens If Omitted or Mismanaged? |
|---|---|---|---|
dp | Array or 2D Table | "What is the mathematically optimal answer for subproblem state ?" | ❌ Without storing subproblems, recursion recomputes states exponentially (). |
rem / i | Table index coordinate | "Which exact capacity or prefix length is being finalized right now?" | ❌ Off-by-one errors (e.g. allocating size instead of ) drop the target state or base case. |
dp[0] | Base state identity | "What is the cost / count for the trivial empty subproblem?" | ❌ Initializing base state to inf or 1 on min-cost corrupts every subsequent table transition. |
float('inf') | Unreachable sentinel | "Is this subproblem capacity impossible to assemble from choices?" | ❌ Forgetting to convert remaining inf to -1 returns invalid large numbers on unreachable inputs. |
coin / choice | Transition candidate | "Which available decision (item, coin, jump) leads from smaller state?" | ❌ In Python, negative index rem - coin < 0 without guards silently reads dp[-1] from the end of the table! |
prev1 / prev2 | Rolling scalar registers | "What are the answers to the immediate 1-2 predecessor states?" | ❌ Updating prev1 before computing curr overwrites state before it can be read. |
tails | Monotonic array | "What is the smallest ending value for an increasing subsequence of length ?" | ❌ Without patience sorting, computing Longest Increasing Subsequence takes quadratic time. |
🧠 The Universal Contract of Dynamic Programming:
- Index Value Contract: The array index
dp[i]is the exact subproblem signature; the stored value is the optimal result for that subproblem.- Dependency Direction Invariant: Outer and inner loops must strictly process states in topological dependency order so every dependency
dp[smaller]is final beforedp[i]is computed.
🌟 The 3 Dimensions of Dynamic Programming & The Tabulation Invariant
Every DP problem is characterized across 3 Fundamental Dimensions:
┌─────────────────────────────────────────────────────────────────────────────┐│ THE 3 DIMENSIONS OF DYNAMIC PROGRAMMING │├───────────────────┬───────────────────────────────────┬─────────────────────┤│ Dimension │ Mechanism in Code │ Question It Answers │├───────────────────┼───────────────────────────────────┼─────────────────────┤│ 1. STATE │ 1D array (`dp[i]`), 2D grid │ "How many variables ││ DIMENSIONALITY │ (`dp[i][j]`), or Bitmask (`dp[m]`│ describe a state?" │├───────────────────┼───────────────────────────────────┼─────────────────────┤│ 2. LOOP │ Forward loop (Unbounded reuse) │ "Can candidates be ││ DIRECTION │ Backward loop (0/1 single-use) │ reused indefinitely?│├───────────────────┼───────────────────────────────────┼─────────────────────┤│ 3. SPACE │ Full table vs 1D rolling row vs │ "Can table memory be││ COMPRESSION │ 2 scalar registers │ safely collapsed?" │└───────────────────┴───────────────────────────────────┴─────────────────────┘ How this plays out in actual problems:
🟢 Scenario A: 1D Knapsack Loop Direction (0/1 vs Unbounded)
- Unbounded Supply (Coin Change LC 322): You can use the same coin multiple times.
- The Code: Loop capacity forwards:
for rem in range(coin, target + 1): dp[rem] = min(dp[rem], dp[rem - coin] + 1). Reading a recently updated cell in the same row allows infinite reuse.
- The Code: Loop capacity forwards:
- Single Use (0/1 Knapsack / Partition Equal Subset Sum LC 416): Each item can be picked at most once.
- The Code: Loop capacity backwards:
for rem in range(target, num - 1, -1): dp[rem] = dp[rem] or dp[rem - num]. Stepping backwards reads strictly from the previous unmodified iteration, forbidding reuse.
- The Code: Loop capacity backwards:
🔵 Scenario B: 2D Sequence Alignment (LCS LC 1143 & Edit Distance LC 72)
- When comparing two strings and of lengths and , subproblems correspond to prefix pairs.
- The Rule: If characters match (
s1[i-1] == s2[j-1]), diagonal transitiondp[i][j] = 1 + dp[i-1][j-1]. If characters mismatch, combine orthogonal pathsdp[i][j] = max(dp[i-1][j], dp[i][j-1]). - Space Compression: Because row depends only on row , compress table to with two rolling rows.
- The Rule: If characters match (
🟣 Scenario C: Monotonic Patience Sorting (Longest Increasing Subsequence LC 300)
- Traditional DP takes by checking all .
- The Rule: Maintain an array
tailswheretails[k]is the smallest tail of all increasing subsequences of length . For each element, use binary searchbisect_leftin to find its insertion position. - The Result: Replaces quadratic scan with optimal patience sorting.
💡 The Ultimate Takeaway Decision Rule:
When analyzing a DP problem, answer the 3 Questions in order:
- State: What is the minimal state signature? (
dp[i]ordp[i][j])- Base Case: What is the free answer for empty input? (
dp[0] = 0ordp[0] = 1)- Transition: Which smaller states combine into
dp[state]?
- If 0/1 items ➔ Backward capacity loop.
- If Unbounded items ➔ Forward capacity loop.
- If Immediate lookback ➔ Collapse table to scalar variables.
🎯 The 5 Essential Dynamic Programming Paradigms & Archetypes
┌──────────────────────────────────────────────────────────────────────────────────────────────────────────────────┐│ THE 5 CORE DYNAMIC PROGRAMMING ARCHETYPES │├────────────────────────┬──────────────────────┬───────────────────────────────┬──────────────────────────────────┤│ Archetype │ State Signature │ Transition Formula │ Space Optimization Bound │├────────────────────────┼──────────────────────┼───────────────────────────────┼──────────────────────────────────┤│ 1. 1D Linear Choice │ `dp[i]` = max loot / │ `dp[i] = max(dp[i-1],` │ $O(1)$ space using two rolling ││ (LC 70 / LC 198) │ ways for prefix $i$ │ ` dp[i-2] + val)` │ scalar variables (`prev1, prev2`)│├────────────────────────┼──────────────────────┼───────────────────────────────┼──────────────────────────────────┤│ 2. Knapsack 0/1 vs Unb.│ `dp[w]` = optimal for│ Unbounded: Forward capacity │ $O(\text{target})$ 1D array; ││ (LC 322 / LC 416) │ capacity $w$ │ 0/1: Backward capacity │ Loop direction controls reuse │├────────────────────────┼──────────────────────┼───────────────────────────────┼──────────────────────────────────┤│ 3. 2D Two-String Align │ `dp[i][j]` = prefix │ Match: $1 + \text{diag}$ │ $O(\min(M, N))$ space using ││ (LC 1143 / LC 72) │ alignment of $s1, s2$│ Mismatch: combine top / left │ 1D rolling row buffer │├────────────────────────┼──────────────────────┼───────────────────────────────┼──────────────────────────────────┤│ 4. Monotonic LIS │ `tails[k]` = min end │ Binary search `bisect_left` │ $O(N \log N)$ time with ││ (LC 300 / LC 354) │ value for length $k$ │ replaces quadratic scan │ $O(N)$ tails array │├────────────────────────┼──────────────────────┼───────────────────────────────┼──────────────────────────────────┤│ 5. State Machine DP │ Multiple registers: │ Discrete transition matrix │ $O(1)$ space tracking state ││ (LC 714 / LC 121) │ `hold, cash` │ between finite system states │ registers across stream │└────────────────────────┴──────────────────────┴───────────────────────────────┴──────────────────────────────────┘ 🏠 1. 1D Linear Choice & Space Optimization (LC 198 — House Robber)
- Mental Model: At house , you either skip house (retaining
dp[i-1]) or rob house (addingnums[i]todp[i-2]). - Code: see the House Robber card.
2. Knapsack & Loop Direction Control (LC 322 — Coin Change)
- Mental Model: Tabulate minimal coins for every amount from 1 to
amount. - Code Blueprint:
def coinChange(coins: list[int], amount: int) -> int: dp = [float('inf')] * (amount + 1) dp[0] = 0 for coin in coins: for rem in range(coin, amount + 1): dp[rem] = min(dp[rem], dp[rem - coin] + 1) return dp[amount] if dp[amount] != float('inf') else -1 🧵 3. 2D Sequence Alignment (LC 1143 — Longest Common Subsequence)
- Mental Model: Compare characters and . If equal, extend diagonal match; otherwise take maximum of deleting from or .
- Code Blueprint:
def longestCommonSubsequence(text1: str, text2: str) -> int: M, N = len(text1), len(text2) dp = [0] * (N + 1) for i in range(1, M + 1): curr = [0] * (N + 1) for j in range(1, N + 1): if text1[i - 1] == text2[j - 1]: curr[j] = 1 + dp[j - 1] else: curr[j] = max(dp[j], curr[j - 1]) dp = curr return dp[N] 📈 4. Patience Sorting & Monotonic DP (LC 300 — LIS)
- Mental Model: Maintain the smallest tail elements of increasing subsequences to maximize extension opportunities for future incoming values.
- Code: see the LIS card.
💼 5. State Machine DP (LC 714 — Stock with Transaction Fee)
- Mental Model: Explicitly model finite operational states (
hold,cash) with mutual transitions; the fee is paid once per completed trade, on the sell edge. - Code Blueprint:
def maxProfit(prices: list[int], fee: int) -> int: hold, cash = -prices[0], 0 # best profit while holding a share / holding none for p in prices[1:]: hold, cash = max(hold, cash - p), max(cash, hold + p - fee) return cash 🌳 Evaluating Subproblems, State Transitions & Space Optimization Invariants
Refactoring and optimizing dynamic programming solutions requires rigorous adherence to state invariants:
1. The Two-Phase Optimization Process
- Phase 1 (Correctness First): Write out the full 2D or 1D tabulation table. Verify all base cases, transitions, and boundary conditions.
- Phase 2 (Space Optimization): Only after the table is verified correct, compress dimensions if transitions look back only a constant distance. If the problem requires path reconstruction (returning the actual sequence of coins/words), you must preserve the full table.
2. Guarding Negative Indices
- In Python, negative index
dp[-1]is valid syntax that accesses the last element of the list. Always verifyrem - coin >= 0before indexing to prevent silent table corruption.
💡 Staff SWE Architectural Invariant:
Dynamic programming is mathematical induction realized as software. The loop ordering guarantees the inductive hypothesis: when computing state , all required dependencies are already fully computed, immutable, and optimal.
Understanding Invariants: Optimal Substructure & Dependency Order
When I compute dp[i], every smaller state it depends on is already final and correct. The loop order is what guarantees that.
DP transforms exponential recursion into polynomial tabulation by evaluating states in topological dependency order and storing optimal answers in an indexed table.
Iterating backward in 0/1 knapsack prevents an item from being used multiple times in the same pass.
Without grounding base cases, recurrence transitions cannot propagate correct values to target states.
Common Questions
"Are top-down (memoized recursion) and bottom-up (tabulation) actually different algorithms, or is it just two names for the same thing?"
They're the same recurrence, the same state, and the same transition — the only thing that differs is how the dependency order gets guaranteed.
Bottom-up commits to an explicit fill order up front (usually smallest state to largest) and trusts that order to guarantee every
dp[i - something]you read has already been written. You, the author, are responsible for proving that order is correct before you write the loop.Top-down writes the recurrence exactly as you'd state it in English — "the answer for
nneeds the answer forn-1andn-2" — as a plain recursive function, with a cache (@lru_cacheor amemodict) added so the same state is never recomputed. The dependency order takes care of itself: the call stack naturally computes whatever a state depends on before that state can return, because it can't return until its recursive calls do. You never have to reason about fill order at all — recursion does it for you.That's why converting between them on request is a strong signal in an interview: if you can write one, you already know the state, the transition, and the base case, which is the entire content of the algorithm — the loop-vs-recursion shell around it is just implementation. Top-down is usually easier to derive first, because you think in terms of the recurrence, not the order. Bottom-up is usually easier to optimize for space afterward (e.g. collapsing a full table to two rolling variables), because the explicit fill order makes it obvious which past states you can safely discard.
Coach discussion points
- 1.
"Why not just take the biggest coin that fits each time? Give me an input where that loses." —
coins = [1, 3, 4], amount = 6. Tests whether the student knows why they are doing DP or is pattern-matching on the word "minimum". The highest-signal opener in this pattern. - 2.
"Say your
dp[i]out loud as an English sentence." — A student who cannot finish the sentence has not defined the state, and every bug after that traces back to it. Do this before looking at any code. - 3.
"Your table has 12 cells and you only ever read two of them at a time. What could you delete?" — Leads to the rolling-variable optimisation by discovery. Follow-up: "and when would that optimisation cost you something you need?" (Reconstruction.)
- 4.
"What is the same about your solution and the naive recursion, and what is different?" — The recurrence is identical; only the caching differs. A student who sees this can convert freely between top-down and bottom-up, which is what the interviewer will ask for next.
- 5.
"Your Wildcard Matching solution passes. Now swap
'*'for regex semantics -- what breaks?" — Tests whether the student understands that regex's'*'is bonded to the preceding element, not a free-standing wildcard. A student who just changes'?'to'.'and keeps the same'*'transition will fail immediately on"aa"matching"a*". - 6.
"Walk me through why
dp[0][j] = dp[0][j-2]in regex butdp[0][j] = dp[0][j-1]in wildcard." — Forces the student to articulate the element-pairing invariant out loud: regex's'*'always consumes 2 pattern positions (the element plus the star) when skipped, while wildcard's'*'is its own standalone unit consuming 1.
Complexity analysis
Coin Change — Time O(amount × len(coins)), Space O(amount).
The outer loop runs amount times; the inner loop tries every coin at each step. With amount ≤ 104 and ≤ 12 coins, that is at most 120,000 operations. Compare with the naive recursion, which explores every combination and is exponential — roughly O(len(coins)^amount). DP is what turns exponential into a product of two small numbers, and being able to state both bounds is the point of the question.
House Robber — Time O(n), Space O(1) after the rolling-variable optimisation (O(n) before it). One pass, constant work per house.
LCS — Time O(m × n), Space O(m × n), reducible to O(min(m, n)) by keeping only the previous row. Note the space reduction costs you the ability to reconstruct the actual subsequence afterwards — you can still get its length. If the interviewer asks for the string itself, you need the full table (or a cleverer method). Say that trade-off out loud; it is a real one.
The general shape: DP cost is (number of states) × (cost of one transition). Say it that way rather than pattern-matching a formula. O(amount × coins), O(n × 1), O(m × n × 1) all fall out of it immediately, and so does any unfamiliar DP problem.
A vending machine must give change for £1.37 using the fewest coins possible. Grabbing the largest coin that fits each time — the greedy instinct — happens to work for British coins, but it fails outright for other coin sets: with coins {1, 3, 4} making 6, greedy takes 4 + 1 + 1 = 3 coins while the true answer is 3 + 3 = 2. The machine cannot rely on the greedy shortcut, so it builds a table of "fewest coins for 1p, for 2p, for 3p…" up to the amount required, each row using the rows below it. Compilers do this for instruction selection, and bioinformatics does it for sequence alignment.
💡 Don't worry if identifying DP states feels challenging right now! Dynamic Programming is simply recursion with memory: caching overlapping subproblems to turn exponential trees into polynomial grids. As you progress through the Archetype Variants (from Climbing Stairs and Coin Change to Longest Increasing Subsequence and Edit Distance), each hands-on challenge will cement this intuition until defining dp[i] state transitions and base cases becomes second nature.
Recomputing overlapping subproblems recursively without memoization: Naive recursion branches exponentially computing
ways(n-1) + ways(n-2). Memoization or bottom-up tabulation reduces this to .Off-by-one on base cases: Reaching step 1 has 1 way; reaching step 2 has 2 ways (
1+1and2). Settingdp[2] = 1offsets all subsequent stairs.Allocating array space when suffices: Storing the entire DP table consumes space. Because step only depends on and , two rolling variables
prev1, prev2suffice.
Staff+ Systems Architecture & Hardware Considerations
Triggers: "maximum profit / minimum cost", "number of distinct ways to reach state", "can reach target boolean", "optimal substructure + overlapping subproblems". Decisions at state depend strictly on optimal solutions to smaller subproblems.
State space dimensionality (1D, 2D, ...). For states with transitions, runtime is . Memory must be managed carefully: transitions depending only on the immediate prior row or step allow rolling array space compression from down to or .
Topological ordering violations (attempting to compute before its dependency subproblems are settled); incorrect base case initialization (e.g. initializing min-cost DP with 0 instead of infinity); off-by-one indices between DP table and 0-indexed input arrays.
Conceptual Foundation & Intuitive Analogy
🧭 Conceptual Foundation & Pattern Intuition
Dynamic Programming (DP) is the algorithmic realization of mathematical induction: solving a complex problem by breaking it down into overlapping subproblems and storing subproblem answers to avoid exponential recomputation. A problem exhibits optimal substructure if an optimal solution to the problem contains optimal solutions to its subproblems. In Climbing Stairs, to reach step , you must have taken either a 1-step leap from step or a 2-step leap from step . Therefore, the total distinct ways to reach step is simply the sum: .
🏟️ The Analogy: The Staircase of Milestones
Imagine standing in front of a flight of stairs. You can take either 1 step or 2 steps at a time.
- Step 1 has only 1 way (take 1 step).
- Step 2 has 2 ways (1+1 or a single 2-step jump).
- What about Step 3? To land on Step 3, you must have been on Step 2 (and took 1 step) OR on Step 1 (and took 2 steps). There are no other physical possibilities! So total ways to Step 3 =
ways(2) + ways(1) = 2 + 1 = 3. - What about Step 4? It is simply
ways(3) + ways(2) = 3 + 2 = 5.
You never need to recount steps from the ground floor; you simply add the two numbers written on the steps beneath your feet!
🔑 Why It Works
Notice how the recurrence only looks back 2 steps. We don't need an array of size ; two scalar variables (prev1, prev2) act as a sliding register, collapsing an space table into constant memory!
When I compute dp[i], every smaller state it depends on is already final and correct. The loop order is what guarantees that.
Optimal substructure: DP state dp[i] depends strictly on already-computed subproblems. Rolling array reduces space from O(S) to O(1 tier).
Iterate base cases -> compute states in topological transition order (dp[i] = min/max/sum of transitions).
The 11 Mental Models of Dynamic Programming
Identify the state signature and transition dependency direction before allocating tables.
1Memoization
brute-force recursion ➔ cache results by arguments ➔ each state solved onceMemoized Recursion (Top-Down DP, Memo DFS): a technique for any state shape
| 1 | from typing import Callable, Dict, Hashable, TypeVar |
| 2 | |
| 3 | R = TypeVar("R") |
| 4 | |
| 5 | |
| 6 | def memoize(recurrence: Callable[[Hashable, Callable[[Hashable], R]], R]) -> Callable[[Hashable], R]: |
| 7 | """Memoization: solve(state) with each state's answer computed once and then looked up. |
| 8 | recurrence(state, solve) computes the answer for state, calling solve on smaller states. |
| 9 | Precondition: the answer depends only on state, and the calls never loop back to a state in progress. |
| 10 | S = distinct states. T = the cost of one recurrence call besides the solve calls it makes. |
| 11 | Time: O(S * T) | Space: O(S) memo and recursion stack |
| 12 | """ |
| 13 | # memo: memo[state] holds the finished answer for state, once it has been computed |
| 14 | memo: Dict[Hashable, R] = {} |
| 15 | |
| 16 | def solve(state: Hashable) -> R: |
| 17 | # 1. Compute Once, Then Reuse: |
| 18 | # The first call for a state runs the recurrence and stores the answer before returning, so |
| 19 | # every later call for the same state is a lookup instead of a repeated exploration. |
| 20 | if state not in memo: |
| 21 | memo[state] = recurrence(state, solve) |
| 22 | return memo[state] |
| 23 | |
| 24 | return solve |
The number of ways to decode s[index:] depends only on index, never on how the digits before it were split, so dfs(index) stores its answer in memo[index] the first time it finishes and returns that stored value on every later call. The plain recursion reaches the same index along many different split paths; with the memo, each index explores its one-digit and two-digit branches only once, and every repeated call is a lookup that returns exactly what exploring again would have returned. The trap is the key: memo must be keyed by every argument that changes the answer. Here that is index alone, but in Interleaving String (LC 97) the answer depends on how far both strings are used, so the key is (i, j); key by i alone and a call that has used 2 letters of s2 gets the answer stored for one that used 5.
Gotcha 1 of 5
- The trap
Gotcha 1: Keying
memobyiwhen the answer depends on(i, j)Mistakememo[i] = resFixmemo[(i, j)] = resWhat happens:
memomust be keyed by every argument that changes the answer. In Decode Ways (LC 91), that isindexalone. In Interleaving String (LC 97),dfs(i, j)depends on bothiandj. With the keyi, a call gets the answer stored for a differentj.Example: Interleaving String (LC 97): s1 = "a", s2 = "ab", s3 = "aba"Mistake: returns FalseFix: returns True
2Linear DP
dp[i] = the answer for the first i steps ➔ built from dp[i-1] and dp[i-2] ➔ O(1) rolling registers1D DP (Linear DP)
i is built only from the answers at the last one or two positions: steps of 1 or 2, counts of ways, best totals.| 1 | from typing import Callable |
| 2 | |
| 3 | |
| 4 | def linear_dp(n: int, first_two: tuple[int, int], combine: Callable[[int, int, int], int]) -> int: |
| 5 | """Linear DP: dp[i] is built from dp[i - 1] and dp[i - 2], kept in two rolling variables. |
| 6 | combine(prev1, prev2, i) returns dp[i] from the two answers before it. |
| 7 | Precondition: first_two is (dp[0], dp[1]) and n >= 1. |
| 8 | T = the time of one combine call. |
| 9 | Time: O(N * T) | Space: O(1) |
| 10 | """ |
| 11 | # prev2, prev1: dp[i - 2] and dp[i - 1], the only two answers the next one needs |
| 12 | prev2, prev1 = first_two |
| 13 | for i in range(2, n + 1): |
| 14 | # 1. Build dp[i] From The Last Two Answers: |
| 15 | # Both answers are final, so one call to combine gives dp[i] without looking further back. |
| 16 | curr = combine(prev1, prev2, i) |
| 17 | |
| 18 | # 2. Roll The Window Forward: |
| 19 | # prev2 takes the old prev1 first, because prev1 is overwritten on the next line. |
| 20 | prev2 = prev1 |
| 21 | prev1 = curr |
| 22 | |
| 23 | return prev1 |
dp[i] depends only on dp[i - 1] and dp[i - 2], so keep just those two answers in prev1 and prev2 and move them forward once per step, instead of storing a table. Decide what dp[i] means before writing the formula. Each dp[i] is built from two answers that are already final, so every answer is computed once, in order, and dp[n] is complete when the loop ends. The trap is the shift: set prev2 = prev1 before prev1 = curr, or prev2 is overwritten by the new value and both variables hold the same answer.
Gotcha 1 of 3
- The trap
Gotcha 1: Setting
prev1 = currbeforeprev2 = prev1Mistakeprev1 = curr prev2 = prev1Fixprev2 = prev1 prev1 = currWhat happens:
prev1holdsdp[i - 1]andprev2holdsdp[i - 2]. The nextdp[i - 2]is the oldprev1. Ifprev1 = currruns first, that old value is lost. Thenprev2 = prev1copiescurr, so both variables hold the same value.Example: Climbing Stairs (LC 70): n = 5Mistake: returns 16Fix: returns 8
3Unbounded Knapsack
items & capacities ➔ capacity loop runs upward so an item can repeat ➔ dp[w]Unbounded Knapsack (Coin Change, Coin Change II)
| 1 | def coin_change(coins: list[int], amount: int) -> int: |
| 2 | """Unbounded Knapsack: the fewest coins that make amount, each coin usable any number of times (forward loop). |
| 3 | Time: O(N * amount) | Space: O(amount) |
| 4 | """ |
| 5 | # dp: dp[w] is the fewest coins that make amount w; infinity marks w as not yet reachable |
| 6 | dp = [float('inf')] * (amount + 1) |
| 7 | dp[0] = 0 |
| 8 | for coin in coins: |
| 9 | for w in range(coin, amount + 1): |
| 10 | # 1. Reuse This Coin Forward: |
| 11 | # The forward loop lets dp[w - coin] already include this coin, so one coin may be used any number of times. |
| 12 | dp[w] = min(dp[w], dp[w - coin] + 1) |
| 13 | return int(dp[amount]) if dp[amount] != float('inf') else -1 |
Treat each amount as its own subproblem: dp[w] is the fewest coins that make w, and each coin updates it from dp[w - coin]. Loop w upward, so dp[w - coin] may already include this coin and the coin can repeat. Start from infinity, which marks an amount as not yet reachable, and only dp[0] = 0. The trap is the loop direction: for w in range(coin, amount + 1), not downward, which would use each coin at most once.
Gotcha 1 of 3
- The trap
Gotcha 1: Looping
wdownward when items can be reusedMistakefor w in range(amount, coin - 1, -1):Fixfor w in range(coin, amount + 1):What happens: Going upward,
dp[w - coin]may already include thiscoin, sodp[w]can use it again. That is what 'any number of times' needs. Going downward readsdp[w - coin]before this pass updates it, so each coin is used at most once, which is the 0/1 rule. Withcoins = [2], amount 4 needs the coin twice.Example: coins = [2], amount = 4Mistake: returns -1Fix: returns 2
4Grid DP
grid dp[i][j] ➔ depends on the cell above and the cell to the left ➔ 1D rolling row2D DP: Grid Paths (Unique Paths, Minimum Path Sum)
| 1 | def unique_paths(m: int, n: int) -> int: |
| 2 | """Unique Paths: count right/down paths in an m x n grid with one rolling row. |
| 3 | Time: O(M * N) | Space: O(N) |
| 4 | """ |
| 5 | # row: one rolling row of the DP grid; row[j] starts at 1 since row 0 is reached only by moving right |
| 6 | row = [1] * n |
| 7 | for _ in range(1, m): |
| 8 | for j in range(1, n): |
| 9 | # 1. Combine Above And Left: |
| 10 | # row[j] still holds the count from the row above; add row[j - 1], already updated for this row. |
| 11 | row[j] += row[j - 1] |
| 12 | return row[n - 1] |
Give every grid cell (i, j) one answer, and build it only from the cell above and the cell to its left. Fill the grid row by row, so both cells are already final, and keep just one rolling row: row[j] still holds the answer from above when you add row[j - 1], the answer from the left. The trap is the first column: row[0] has no left neighbour and stays 1, so the inner loop must start at j = 1; starting at 0 reads row[-1], the last cell.
Gotcha 1 of 3
- The trap
Gotcha 1: Starting
jat 0 inunique_pathsMistakefor j in range(0, n):Fixfor j in range(1, n):What happens: Column 0 is reached in exactly one way, so
row[0]must stay 1. Withj = 0, the line readsrow[-1], which is the last cell. Python raises no error. On one column,row[0] += row[0]doubles the cell on every row.Example: m = 5, n = 1Mistake: returns 16Fix: returns 1
50/1 Knapsack
items & capacities ➔ capacity loop runs downward so each item counts once ➔ dp[w]0/1 Knapsack (Partition Equal Subset Sum, Subset Sum)
| 1 | def can_partition(nums: list[int]) -> bool: |
| 2 | """0/1 Knapsack: Partition array into two equal subsets (reverse loop). |
| 3 | Time: O(N * Target) | Space: O(Target) |
| 4 | """ |
| 5 | total = sum(nums) |
| 6 | if total % 2 != 0: |
| 7 | return False |
| 8 | target = total // 2 |
| 9 | # dp: dp[w] is True when sum w is reachable using only the items processed so far |
| 10 | dp = [False] * (target + 1) |
| 11 | dp[0] = True |
| 12 | for x in nums: |
| 13 | for w in range(target, x - 1, -1): |
| 14 | # 1. Use This Item At Most Once: |
| 15 | # The reverse loop reads dp[w - x] before this pass updates it, so x is counted at most once per w. |
| 16 | dp[w] = dp[w] or dp[w - x] |
| 17 | return dp[target] |
Treat each sum as its own subproblem: dp[w] is True when the items seen so far can add up to w, and each item x updates it from dp[w - x]. Loop w downward, so dp[w - x] has not been touched by the current x yet and x is counted at most once; looping upward would let the same x fill dp[w - x] and then dp[w] in one pass. The trap is exactly that loop direction: for w in range(target, x - 1, -1), not range(x, target + 1).
Gotcha 1 of 3
- The trap
Gotcha 1: Looping
wupward in a 0/1 problemMistakefor w in range(x, target + 1):Fixfor w in range(target, x - 1, -1):What happens: Going upward,
dp[w - x]may already include the currentx. Thendp[w]usesxa second time. Herex = 1makes every sum from 1 to 4 reachable, so the target 4 looks reachable. Going downward,dp[w - x]still describes only the items beforex.Example: nums = [1, 2, 5]Mistake: returns TrueFix: returns False
6LIS
array ➔ tails array maintenance ➔ binary search replacementLongest Increasing Subsequence (Patience Sorting)
| 1 | import bisect |
| 2 | |
| 3 | def length_of_lis(nums: list[int]) -> int: |
| 4 | """Longest Increasing Subsequence via Patience Sorting. |
| 5 | Time: O(N log N) | Space: O(N) |
| 6 | """ |
| 7 | # tails: sorted; tails[k] is the smallest last value of any increasing subsequence of length k + 1 seen so far |
| 8 | tails: list[int] = [] |
| 9 | |
| 10 | for x in nums: |
| 11 | # 1. Find Where x Fits: |
| 12 | # bisect_left finds the first tail >= x, the pile x can legally extend or replace. |
| 13 | idx = bisect.bisect_left(tails, x) |
| 14 | if idx == len(tails): |
| 15 | # 2. Start A Longer Subsequence: |
| 16 | # No tail is >= x, so x extends the longest subsequence found so far by one. |
| 17 | tails.append(x) |
| 18 | else: |
| 19 | # 3. Lower An Existing Tail: |
| 20 | # x is smaller than tails[idx], so it leaves more room for later values at this same length. |
| 21 | tails[idx] = x |
| 22 | |
| 23 | return len(tails) |
Keep tails[k] as the smallest last value of any increasing subsequence of length k + 1, and for each x replace the first tail that is >= x (found with bisect_left), or append x when there is none. A smaller tail can only help, because it leaves more room for the values that come later, and replacing never breaks the order of tails, so len(tails) is always the longest length reached so far. The trap is reading tails as the answer: it has the right length but is usually not a real subsequence, so store each element's predecessor index when you must rebuild the sequence.
Gotcha 1 of 3
- The trap
Gotcha 1: Returning
tailsas the subsequenceMistakereturn tailsFixreturn len(tails)What happens:
tails[k]is the smallest last value of any increasing subsequence of lengthk + 1. Its length is right. Its values can come from different subsequences, in the wrong order. To rebuild a real subsequence, store each element's predecessor index.Example: nums = [3, 4, 1]Mistake: returns [1, 4]Fix: returns 2
7State Machine DP
states (hold, sold, rest) ➔ day-by-day transitions ➔ best final stateState Machine DP (Buy/Sell Stock)
| 1 | def max_profit(prices: list[int]) -> int: |
| 2 | """Best Time to Buy and Sell Stock II: 2-state machine, unlimited transactions. |
| 3 | States: hold (own one share), cash (own no share) |
| 4 | Time: O(N) | Space: O(1) |
| 5 | """ |
| 6 | # hold, cash: best profit so far while owning one share (hold) or owning none (cash) |
| 7 | hold = -prices[0] |
| 8 | cash = 0 |
| 9 | |
| 10 | for i in range(1, len(prices)): |
| 11 | p = prices[i] |
| 12 | # 1. Transition Both States From Yesterday: |
| 13 | # hold keeps the share or buys today (cash - p); cash stays out or sells today (hold + p). |
| 14 | # Both right-hand sides read yesterday's hold and cash, before either is overwritten. |
| 15 | hold, cash = max(hold, cash - p), max(cash, hold + p) |
| 16 | |
| 17 | # Ending while still holding a share is never better than ending with it sold. |
| 18 | return cash |
At the end of each day you are in exactly one of two states, owning a share (hold) or not (cash), and each state's best profit follows only from yesterday's two values: hold = max(hold, cash - p) keeps the share or buys today, and cash = max(cash, hold + p) stays out or sells today. Every legal run of buys and sells is a path through these states and each line keeps only the best way to arrive, so the last cash is the best profit of all; a cooldown, a fee or a trade limit just adds a state or a term, as long as every update reads yesterday's values. The trap is the start: hold = -prices[0], not 0, because hold = 0 means owning a share you never paid for, and selling it would add its full price to cash as profit.
Gotcha 1 of 4
- The trap
Gotcha 1: Starting with
hold = 0instead ofhold = -prices[0]Mistakehold = 0Fixhold = -prices[0]What happens:
holdis the best profit while owning one share.hold = 0means owning a share that cost nothing. Selling it adds its full price tocashas profit. Buying on day 0 costsprices[0], sohold = -prices[0].Example: prices = [5, 3]Mistake: returns 3Fix: returns 0
8Interval DP
range dp[i][j] ➔ built from shorter ranges inside it ➔ fill by increasing lengthInterval DP (Longest Palindromic Subsequence)
| 1 | def longest_palindrome_subseq(s: str) -> int: |
| 2 | """Longest Palindromic Subsequence: interval DP over the range s[i..j], filled from short ranges to long ones. |
| 3 | Time: O(N^2) | Space: O(N^2) |
| 4 | """ |
| 5 | n = len(s) |
| 6 | # dp: dp[i][j] is the length of the longest palindromic subsequence of s[i..j]; one letter is a palindrome of length 1 |
| 7 | dp = [[0] * n for _ in range(n)] |
| 8 | for i in range(n): |
| 9 | dp[i][i] = 1 |
| 10 | |
| 11 | # 1. Fill By Increasing Range Length: |
| 12 | # dp[i][j] reads dp[i + 1][j - 1], dp[i + 1][j] and dp[i][j - 1], all shorter ranges, so they must be final first. |
| 13 | for length in range(2, n + 1): |
| 14 | for i in range(n - length + 1): |
| 15 | j = i + length - 1 |
| 16 | # 2. Match The Two Ends, Or Drop One: |
| 17 | # Equal end letters wrap the answer for the inside range with 2 more; otherwise one end cannot be used, so drop it. |
| 18 | if s[i] == s[j]: |
| 19 | dp[i][j] = dp[i + 1][j - 1] + 2 |
| 20 | else: |
| 21 | dp[i][j] = max(dp[i + 1][j], dp[i][j - 1]) |
| 22 | |
| 23 | return dp[0][n - 1] |
Give every range s[i..j] one answer, dp[i][j], and build it only from shorter ranges inside it: when the two end letters match, they wrap the answer for the inside range dp[i + 1][j - 1] with 2 more; when they differ, one of them cannot be used, so take the better of dropping the left end (dp[i + 1][j]) or the right end (dp[i][j - 1]). Every shorter range is final before it is read, because the table is filled by increasing range length. The trap is the fill order: looping i upward row by row reads dp[i + 1][j - 1] while it is still 0, so fill by length, short ranges first.
Gotcha 1 of 3
- The trap
Gotcha 1: Filling
dprow by row fromi = 0Mistakefor i in range(n): for j in range(i + 1, n):Fixfor length in range(2, n + 1): for i in range(n - length + 1): j = i + length - 1What happens:
dp[i][j]readsdp[i + 1][j - 1]anddp[i + 1][j], which belong to rows further down the table. A loop that runsiupward from 0 reads those cells while they are still 0, so the answer is too small. Fill bylength, short ranges first, or runifromn - 1down to 0.Example: s = "bbbab"Mistake: returns 2Fix: returns 4
9Probability DP
state probability dp[s] ➔ spread over the equally likely moves each step ➔ total on the states that countProbability DP (Knight Probability, New 21 Game)
| 1 | def knight_probability(n: int, k: int, row: int, column: int) -> float: |
| 2 | """Probability DP: spread each square's probability over the 8 knight moves, k times, and total what stays on the board. |
| 3 | Time: O(K * N^2) | Space: O(N^2) |
| 4 | """ |
| 5 | moves = [(1, 2), (2, 1), (2, -1), (1, -2), (-1, -2), (-2, -1), (-2, 1), (-1, 2)] |
| 6 | # dp: dp[r][c] is the probability that the knight stands on (r, c) after the moves made so far, never having left the board |
| 7 | dp = [[0.0] * n for _ in range(n)] |
| 8 | dp[row][column] = 1.0 |
| 9 | |
| 10 | for _ in range(k): |
| 11 | nxt = [[0.0] * n for _ in range(n)] |
| 12 | for r in range(n): |
| 13 | for c in range(n): |
| 14 | # 1. Spread Each Square's Probability Over The 8 Moves: |
| 15 | # Each move has chance 1/8, so a square passes dp[r][c] / 8 to every target that is still on the board. |
| 16 | for dr, dc in moves: |
| 17 | nr, nc = r + dr, c + dc |
| 18 | if 0 <= nr < n and 0 <= nc < n: |
| 19 | nxt[nr][nc] += dp[r][c] / 8 |
| 20 | # 2. Replace The Board With The New Step: |
| 21 | # The share that fell off the board is added nowhere, so it is gone for every later step. |
| 22 | dp = nxt |
| 23 | |
| 24 | # 3. Add Up What Is Left On The Board: |
| 25 | # Each square holds the probability of being there after k moves without leaving, so their total is the answer. |
| 26 | return sum(sum(line) for line in dp) |
Give every state the probability of being there after the steps made so far, and build the next step by passing each state's share to the states it can move to: with 8 equally likely moves, a square passes dp[r][c] / 8 to each target. A target off the board adds nothing, so that share is lost for good. Build the new step in a fresh board nxt and replace dp after the pass, so a share is never passed on twice in one step. The trap is the chance of each move: pass dp[r][c] / 8, not dp[r][c], or the table counts paths and the answer is far above 1.
Gotcha 1 of 3
- The trap
Gotcha 1: Passing the whole probability instead of one eighth
Mistakenxt[nr][nc] += dp[r][c]Fixnxt[nr][nc] += dp[r][c] / 8What happens: A knight picks one of its 8 moves with equal chance, so each target receives one eighth of the square's probability. Without the division, each target receives the whole probability. The table then counts paths, and the answer is far above 1.
Example: n = 3, k = 2, row = 0, column = 0Mistake: returns 4.0Fix: returns 0.0625
10Bitmask DP
about 20 items ➔ bitmask of used items ➔ dp[mask]Bitmask DP (Shortest Path Visiting All Nodes, TSP)
| 1 | def minimum_xor_sum(nums1: list[int], nums2: list[int]) -> int: |
| 2 | """Minimum XOR Sum of Two Arrays: bitmask DP over which numbers of nums2 are already paired. |
| 3 | Time: O(N * 2^N) | Space: O(2^N) |
| 4 | """ |
| 5 | n = len(nums2) |
| 6 | # dp: dp[mask] is the least XOR sum pairing the first popcount(mask) numbers of nums1 with the nums2 set in mask |
| 7 | dp = [float("inf")] * (1 << n) |
| 8 | dp[0] = 0 |
| 9 | |
| 10 | for mask in range(1 << n): |
| 11 | # 1. Find The Next nums1 Index From The Mask: |
| 12 | # The count of set bits is how many nums1 numbers are already paired, so the next one is nums1[i]. |
| 13 | i = bin(mask).count("1") |
| 14 | if i == n: |
| 15 | continue |
| 16 | for j in range(n): |
| 17 | if not mask & (1 << j): |
| 18 | # 2. Pair nums1[i] With A Free nums2[j]: |
| 19 | # mask | (1 << j) is always larger than mask, so this same upward loop reaches it later |
| 20 | # with dp[mask] already final; keep the smaller total found for that larger state. |
| 21 | nxt = mask | (1 << j) |
| 22 | dp[nxt] = min(dp[nxt], dp[mask] + (nums1[i] ^ nums2[j])) |
| 23 | |
| 24 | return dp[(1 << n) - 1] |
When n is small, keep one best answer per set of used items and write the set as the bits of an integer: dp[mask] is the least XOR sum after pairing the first i numbers of nums1 with the nums2 numbers whose bits are set in mask, where i = bin(mask).count("1"). From each mask, pair nums1[i] with every free nums2[j] (not mask & (1 << j)) and keep the smaller total in dp[mask | (1 << j)]. This is correct because the rest of the pairing depends only on which nums2 numbers are used, not on the order they were used in, so the n! orders collapse into 2^n states; and mask | (1 << j) is always larger than mask, so an upward loop over mask finishes every state before it is read. The trap is tracking the nums1 index yourself: pairing any nums1[i] with the mask does not record which nums1 numbers are already used, so one can be paired twice. i must come from the mask.
Gotcha 1 of 5
- The trap
Gotcha 1: Looping over every
iinstead ofi = bin(mask).count("1")Mistakefor i in range(n):Fixi = bin(mask).count("1")What happens:
maskrecords whichnums2numbers are used. It does not record whichnums1numbers are used. The count of set bits is how manynums1numbers are paired, so the next one isnums1[i]. A loop over everyican pair the samenums1number again and again.Example: nums1 = [2, 4, 8], nums2 = [1, 1, 1]Mistake: returns 9Fix: returns 17
11Digit DP
limit n ➔ fill digits left to right with a tight flag ➔ countDigit DP
n (up to 10^9 or more) share some digit property: how many contain a 1, how many can be written from a given digit set, how many have no repeated digit. Checking each number one by one is far too slow.| 1 | from functools import lru_cache |
| 2 | |
| 3 | def count_digit_one(n: int) -> int: |
| 4 | """Number of Digit One: digit DP over the digits of n, keeping whether the prefix still equals n's. |
| 5 | Time: O(D^2 * 10) | Space: O(D^2) |
| 6 | """ |
| 7 | # digits: n's digits, most significant first; size is how many digit positions the walk fills |
| 8 | digits = [int(c) for c in str(n)] |
| 9 | size = len(digits) |
| 10 | |
| 11 | @lru_cache(maxsize=None) |
| 12 | def count(pos: int, ones: int, tight: bool) -> int: |
| 13 | """The 1s in every number that finishes this prefix, which already holds `ones` 1s.""" |
| 14 | # 1. Finish A Number: |
| 15 | # Every digit is placed; the finished number contributes the 1 digits it already holds. |
| 16 | if pos == size: |
| 17 | return ones |
| 18 | # 2. Cap This Digit While Tight: |
| 19 | # tight means the prefix still equals n's digits, so this digit may not pass n's digit here. |
| 20 | top = digits[pos] if tight else 9 |
| 21 | total = 0 |
| 22 | for d in range(top + 1): |
| 23 | # 3. Place Digit d And Stay Tight Only On n's Own Digit: |
| 24 | # A digit below top makes every later digit free (0-9), so tight must carry forward only |
| 25 | # when it was already tight and d matches n's digit exactly here. |
| 26 | total += count(pos + 1, ones + (d == 1), tight and d == top) |
| 27 | return total |
| 28 | |
| 29 | return count(0, 0, True) |
Build every number up to n digit by digit, from the most significant digit, and keep one bit of history about the limit: tight, whether the digits placed so far equal n's. While tight, the next digit may not pass n's digit there; once a smaller digit has been placed, every later digit is free from 0 to 9. Add whatever extra fact the question needs to the state, here ones, the count of 1 digits placed so far, and memoize on the whole state: count(pos, ones, tight). This is correct because two prefixes with the same (position, extra fact, tight) finish in exactly the same set of ways, so each state needs solving only once, and the base case at pos == size reads off the answer for a finished number. The trap is the tight bit: the next position stays tight only when tight and d == top, never d == top alone. Dropping the tight and part re-caps a number that is already smaller than n, undercounting it.
Gotcha 1 of 4
- The trap
Gotcha 1: Writing
d == topinstead oftight and d == topMistaketotal += count(pos + 1, ones + (d == 1), d == top)Fixtotal += count(pos + 1, ones + (d == 1), tight and d == top)What happens: Once a digit below
n's digit is placed, the number is already smaller thann. Every later digit is then free from 0 to 9. Withd == topalone, a later 9 setstightto True again. The next digit is then capped atn's digit, and some numbers are never counted.Example: n = 100Mistake: returns 20Fix: returns 21
Built on the mental models above
- Best Sightseeing PairBest Left Half Carry (Best Sightseeing Pair)
The score of a pair splits into one term for the left spot and one term for the right spot, so one carried value,
best_left, is the whole state. - Kadane's AlgorithmKadane's Algorithm (Maximum Subarray)
The state is the best sum of a subarray that ends at
i, and each step either extends it or starts fresh ati. - Maximum Product SubarrayKadane's Algorithm with a Product (Maximum Product Subarray)
A negative number turns the smallest product into the largest, so keep both
hiandlo, the largest and smallest product of a subarray that ends here. - Circular KadaneKadane's Algorithm on a Circular Array (Maximum Sum Circular Subarray)
A run may wrap around the end, and that run is the total minus the worst plain run, so run Kadane a second time with
minand keep the total. - Max Absolute Subarray SumKadane's Algorithm for the Best and the Worst Run (Maximum Absolute Sum of Any Subarray)
The answer is an absolute value, so run Kadane twice, with
maxand withmin, let each run restart at 0, and take the larger ofcurr_maxand-curr_min. - Turbulent SubarrayKadane's Algorithm with a Direction (Longest Turbulent Subarray)
A run grows only when its next step goes the opposite way, so keep one length per direction of the last step,
upanddown, and flip them on each step. - Kadane with One DeletionKadane's Algorithm with One Deletion (Maximum Subarray Sum with One Deletion)
One number may be deleted, so keep a second state,
drop: the best sum ending here with one number deleted. Deletingxtakes the oldkeep. - House RobberHouse Robber (Non-Adjacent Maximum Sum)
Each item is now take or skip, and taking item
irules out itemi - 1, so the recurrence becomesdp[i] = max(dp[i - 1], dp[i - 2] + x). - Two-Sequence DPTwo-Sequence DP (Longest Common Subsequence, Edit Distance)
The two axes of the table are the prefixes of two sequences, and a cell also looks at the cell diagonally up and to the left.
- Distinct SubsequencesDistinct Subsequences Counting DP
It counts the ways one string can be picked out of another, so each cell adds counts instead of taking a best value.
- Last-Char Counting DPLast-Character Counting DP (Distinct Subsequences II)
The mode is the last letter used, with up to 26 modes, and every count is updated together on each character.
- Burst BalloonsBurst Balloons (Choose the Last Item in a Range)
Each range also chooses the last item handled inside it, and that choice splits the range into two independent halves.
- Minimax DPGame Theory / Minimax DP (Stone Game, Predict the Winner)
Two players take turns on one range of items, and each cell keeps the score difference for the player to move.
The Dynamic Programming Decision Rule
When facing an unseen optimization or counting problem, ask in this order:
Keep hi and lo, the largest and smallest product of a subarray that ends at x, and update both from x, hi * x and lo * x.
Run Kadane twice, once with max for the best plain run and once with min for the worst, keep the total, and take the larger of best and total - worst.
Run Kadane twice, with max for the best run and min for the worst run, each restarting at 0, and take the larger of curr_max and -curr_min.
Keep up and down, the longest run ending here whose last step went up or down; a step up extends down, a step down extends up, and an equal step restarts both.
Keep keep and drop, the best run ending here with nothing deleted and with one number deleted; drop = max(keep, drop + x) is computed before keep is updated.
At each number, either extend the best run that ends just before it or start fresh at it: curr = max(x, curr + x), and keep the largest curr.
Regroup the score as (values[i] + i) + (values[j] - j), carry best_left, the largest values[i] + i of the spots before j, and score each j against it before you update best_left with j.
dp[i] = max(dp[i - 1], dp[i - 2] + x): skip the item, or take it on top of the best from two back.
Maintain rolling registers a, b = b, transition(a, b) in O(1) space.
dp[i][j] = dp[i-1][j], plus dp[i-1][j-1] when s[i-1] == t[j-1]; every dp[i][0] = 1.
Keep one running count per last letter, ends[c]; on each character, ends[ch] = sum(ends) + 1, replacing the old ends[ch], never adding to it.
Define dp[i][j] over the prefixes text1[:i] and text2[:j]; a match builds on the diagonal cell, and a mismatch combines the cell above and the cell to the left.
Define dp[i][j] for grid cell (i, j) and combine the cell above and the cell to the left, keeping one rolling row.
Index dp by the capacity and loop it downward for each item, so an item is used at most once.
Index dp by the capacity and loop it upward for each item, so an item may repeat; for counting combinations keep the items in the outer loop.
Maintain tails array with bisect_left in O(N log N); for envelopes, sort by width ascending and height descending first.
Keep one best value per state and update every state from the previous step's values.
dp[i][j] = best over k of dp[i][k] + dp[k][j] + cost(i, k, j), where k is the LAST item handled between i and j; fill shorter intervals first.
Define dp[i][j] for the range i..j, fill by increasing range length, and build each cell from shorter ranges inside it.
dp[state] = best over moves of (gain of the move - dp[next state]): the score difference for the player to move.
Index dp by a bitmask of the used items (plus the last item when it matters) and fill masks in increasing order.
Fill digits left to right, carrying a tight flag (still equal to n's prefix) and the property's state; memoize the states.
Let dp[state] be the probability of being in a state after the steps made so far, pass each state's share to the states it can move to, and total the states that count.
Cache results by the arguments (@cache), so each state is solved once.
Pattern Architecture & Invariant Design Masterclass
Dynamic programming is one observation applied ruthlessly: a big problem's answer is built from smaller versions of the same problem, and the same small versions keep coming up. Compute each small version once, write it down, and look it up thereafter. That is the whole idea. Everything else is bookkeeping.
Two conditions must both hold, and naming them is how you recognise a DP problem rather than guessing:
- Optimal substructure — the best answer to the whole contains the best answers to its parts. The cheapest way to make 11 cents is one coin plus the cheapest way to make (11 − that coin) cents.
- Overlapping subproblems — the same parts are needed over and over. Naive recursion for "make 11 cents" recomputes "make 6 cents" an exponential number of times.
If only condition 1 holds, you have divide and conquer (see dfs.md), not DP — merge sort never solves the same half twice, so there is nothing to cache.
The three questions that turn any DP problem into code, in this exact order:
- What is the state? What is the smallest set of facts that fully describes a sub-question? (Here: "the amount I am trying to make." One number.)
- What is the transition? How is one state's answer built from smaller states' answers? (Here:
dp[i] = min over coins of dp[i − coin] + 1.) - What is the base case? Which state's answer is known without computing anything? (Here:
dp[0] = 0— making zero costs zero coins.)
🔬 Variable Anatomy: The 7 Variables Every DP Solution Uses
To connect abstract dynamic programming recurrences with concrete Python syntax, here is the universal code anatomy showing what every variable does:
def dpMasterTemplate( nums: list[int], target: int, coins: list[int]) -> tuple[int, int, int]: # ========================================================================= # 1. THE STATE TABLES & MEMORY BUFFERS # ========================================================================= # Table sized target + 1; initialized to unreachable sentinel dp = [float('inf')] * (target + 1) # 📊 Tabulation Table: dp[i] = optimal answer for amount i dp[0] = 0 # 🏁 Base State Identity: 0 cost to form 0 amount # Rolling registers for O(1) space optimization (Climbing Stairs / House Robber) prev2, prev1 = 0, 0 # 🔄 Constant-Space Sliding Registers # Patience sorting tails array for O(N log N) LIS tails = [] # 📈 Monotonic Subsequence Thresholds # ========================================================================= # 2. 1D UNBOUNDED KNAPSACK TABULATION (COIN CHANGE) # ========================================================================= for rem in range(1, target + 1): for coin in coins: # Transition Guard: ensure subproblem is non-negative and reachable if rem - coin >= 0 and dp[rem - coin] != float('inf'): # Combine: Bellman optimality principle dp[rem] = min(dp[rem], dp[rem - coin] + 1) min_coins = dp[target] if dp[target] != float('inf') else -1 # ========================================================================= # 3. 1D LINEAR CHOICE TRANSITION (HOUSE ROBBER) # ========================================================================= for x in nums: # dp[i] = max(dp[i-1], dp[i-2] + x) curr = max(prev1, prev2 + x) prev2, prev1 = prev1, curr max_loot = prev1 # ========================================================================= # 4. MONOTONIC PATIENCE SORTING (LIS) # ========================================================================= import bisect for x in nums: idx = bisect.bisect_left(tails, x) if idx == len(tails): tails.append(x) else: tails[idx] = x # Lower threshold for future candidates lis_length = len(tails) return min_coins, max_loot, lis_length Variable Role Reference:
| Variable | Role in Code | Question It Answers | ❌ What Happens If Omitted or Mismanaged? |
|---|---|---|---|
dp | Array or 2D Table | "What is the mathematically optimal answer for subproblem state ?" | ❌ Without storing subproblems, recursion recomputes states exponentially (). |
rem / i | Table index coordinate | "Which exact capacity or prefix length is being finalized right now?" | ❌ Off-by-one errors (e.g. allocating size instead of ) drop the target state or base case. |
dp[0] | Base state identity | "What is the cost / count for the trivial empty subproblem?" | ❌ Initializing base state to inf or 1 on min-cost corrupts every subsequent table transition. |
float('inf') | Unreachable sentinel | "Is this subproblem capacity impossible to assemble from choices?" | ❌ Forgetting to convert remaining inf to -1 returns invalid large numbers on unreachable inputs. |
coin / choice | Transition candidate | "Which available decision (item, coin, jump) leads from smaller state?" | ❌ In Python, negative index rem - coin < 0 without guards silently reads dp[-1] from the end of the table! |
prev1 / prev2 | Rolling scalar registers | "What are the answers to the immediate 1-2 predecessor states?" | ❌ Updating prev1 before computing curr overwrites state before it can be read. |
tails | Monotonic array | "What is the smallest ending value for an increasing subsequence of length ?" | ❌ Without patience sorting, computing Longest Increasing Subsequence takes quadratic time. |
🧠 The Universal Contract of Dynamic Programming:
- Index Value Contract: The array index
dp[i]is the exact subproblem signature; the stored value is the optimal result for that subproblem.- Dependency Direction Invariant: Outer and inner loops must strictly process states in topological dependency order so every dependency
dp[smaller]is final beforedp[i]is computed.
🌟 The 3 Dimensions of Dynamic Programming & The Tabulation Invariant
Every DP problem is characterized across 3 Fundamental Dimensions:
┌─────────────────────────────────────────────────────────────────────────────┐│ THE 3 DIMENSIONS OF DYNAMIC PROGRAMMING │├───────────────────┬───────────────────────────────────┬─────────────────────┤│ Dimension │ Mechanism in Code │ Question It Answers │├───────────────────┼───────────────────────────────────┼─────────────────────┤│ 1. STATE │ 1D array (`dp[i]`), 2D grid │ "How many variables ││ DIMENSIONALITY │ (`dp[i][j]`), or Bitmask (`dp[m]`│ describe a state?" │├───────────────────┼───────────────────────────────────┼─────────────────────┤│ 2. LOOP │ Forward loop (Unbounded reuse) │ "Can candidates be ││ DIRECTION │ Backward loop (0/1 single-use) │ reused indefinitely?│├───────────────────┼───────────────────────────────────┼─────────────────────┤│ 3. SPACE │ Full table vs 1D rolling row vs │ "Can table memory be││ COMPRESSION │ 2 scalar registers │ safely collapsed?" │└───────────────────┴───────────────────────────────────┴─────────────────────┘ How this plays out in actual problems:
🟢 Scenario A: 1D Knapsack Loop Direction (0/1 vs Unbounded)
- Unbounded Supply (Coin Change LC 322): You can use the same coin multiple times.
- The Code: Loop capacity forwards:
for rem in range(coin, target + 1): dp[rem] = min(dp[rem], dp[rem - coin] + 1). Reading a recently updated cell in the same row allows infinite reuse.
- The Code: Loop capacity forwards:
- Single Use (0/1 Knapsack / Partition Equal Subset Sum LC 416): Each item can be picked at most once.
- The Code: Loop capacity backwards:
for rem in range(target, num - 1, -1): dp[rem] = dp[rem] or dp[rem - num]. Stepping backwards reads strictly from the previous unmodified iteration, forbidding reuse.
- The Code: Loop capacity backwards:
🔵 Scenario B: 2D Sequence Alignment (LCS LC 1143 & Edit Distance LC 72)
- When comparing two strings and of lengths and , subproblems correspond to prefix pairs.
- The Rule: If characters match (
s1[i-1] == s2[j-1]), diagonal transitiondp[i][j] = 1 + dp[i-1][j-1]. If characters mismatch, combine orthogonal pathsdp[i][j] = max(dp[i-1][j], dp[i][j-1]). - Space Compression: Because row depends only on row , compress table to with two rolling rows.
- The Rule: If characters match (
🟣 Scenario C: Monotonic Patience Sorting (Longest Increasing Subsequence LC 300)
- Traditional DP takes by checking all .
- The Rule: Maintain an array
tailswheretails[k]is the smallest tail of all increasing subsequences of length . For each element, use binary searchbisect_leftin to find its insertion position. - The Result: Replaces quadratic scan with optimal patience sorting.
💡 The Ultimate Takeaway Decision Rule:
When analyzing a DP problem, answer the 3 Questions in order:
- State: What is the minimal state signature? (
dp[i]ordp[i][j])- Base Case: What is the free answer for empty input? (
dp[0] = 0ordp[0] = 1)- Transition: Which smaller states combine into
dp[state]?
- If 0/1 items ➔ Backward capacity loop.
- If Unbounded items ➔ Forward capacity loop.
- If Immediate lookback ➔ Collapse table to scalar variables.
🎯 The 5 Essential Dynamic Programming Paradigms & Archetypes
┌──────────────────────────────────────────────────────────────────────────────────────────────────────────────────┐│ THE 5 CORE DYNAMIC PROGRAMMING ARCHETYPES │├────────────────────────┬──────────────────────┬───────────────────────────────┬──────────────────────────────────┤│ Archetype │ State Signature │ Transition Formula │ Space Optimization Bound │├────────────────────────┼──────────────────────┼───────────────────────────────┼──────────────────────────────────┤│ 1. 1D Linear Choice │ `dp[i]` = max loot / │ `dp[i] = max(dp[i-1],` │ $O(1)$ space using two rolling ││ (LC 70 / LC 198) │ ways for prefix $i$ │ ` dp[i-2] + val)` │ scalar variables (`prev1, prev2`)│├────────────────────────┼──────────────────────┼───────────────────────────────┼──────────────────────────────────┤│ 2. Knapsack 0/1 vs Unb.│ `dp[w]` = optimal for│ Unbounded: Forward capacity │ $O(\text{target})$ 1D array; ││ (LC 322 / LC 416) │ capacity $w$ │ 0/1: Backward capacity │ Loop direction controls reuse │├────────────────────────┼──────────────────────┼───────────────────────────────┼──────────────────────────────────┤│ 3. 2D Two-String Align │ `dp[i][j]` = prefix │ Match: $1 + \text{diag}$ │ $O(\min(M, N))$ space using ││ (LC 1143 / LC 72) │ alignment of $s1, s2$│ Mismatch: combine top / left │ 1D rolling row buffer │├────────────────────────┼──────────────────────┼───────────────────────────────┼──────────────────────────────────┤│ 4. Monotonic LIS │ `tails[k]` = min end │ Binary search `bisect_left` │ $O(N \log N)$ time with ││ (LC 300 / LC 354) │ value for length $k$ │ replaces quadratic scan │ $O(N)$ tails array │├────────────────────────┼──────────────────────┼───────────────────────────────┼──────────────────────────────────┤│ 5. State Machine DP │ Multiple registers: │ Discrete transition matrix │ $O(1)$ space tracking state ││ (LC 714 / LC 121) │ `hold, cash` │ between finite system states │ registers across stream │└────────────────────────┴──────────────────────┴───────────────────────────────┴──────────────────────────────────┘ 🏠 1. 1D Linear Choice & Space Optimization (LC 198 — House Robber)
- Mental Model: At house , you either skip house (retaining
dp[i-1]) or rob house (addingnums[i]todp[i-2]). - Code: see the House Robber card.
2. Knapsack & Loop Direction Control (LC 322 — Coin Change)
- Mental Model: Tabulate minimal coins for every amount from 1 to
amount. - Code Blueprint:
def coinChange(coins: list[int], amount: int) -> int: dp = [float('inf')] * (amount + 1) dp[0] = 0 for coin in coins: for rem in range(coin, amount + 1): dp[rem] = min(dp[rem], dp[rem - coin] + 1) return dp[amount] if dp[amount] != float('inf') else -1 🧵 3. 2D Sequence Alignment (LC 1143 — Longest Common Subsequence)
- Mental Model: Compare characters and . If equal, extend diagonal match; otherwise take maximum of deleting from or .
- Code Blueprint:
def longestCommonSubsequence(text1: str, text2: str) -> int: M, N = len(text1), len(text2) dp = [0] * (N + 1) for i in range(1, M + 1): curr = [0] * (N + 1) for j in range(1, N + 1): if text1[i - 1] == text2[j - 1]: curr[j] = 1 + dp[j - 1] else: curr[j] = max(dp[j], curr[j - 1]) dp = curr return dp[N] 📈 4. Patience Sorting & Monotonic DP (LC 300 — LIS)
- Mental Model: Maintain the smallest tail elements of increasing subsequences to maximize extension opportunities for future incoming values.
- Code: see the LIS card.
💼 5. State Machine DP (LC 714 — Stock with Transaction Fee)
- Mental Model: Explicitly model finite operational states (
hold,cash) with mutual transitions; the fee is paid once per completed trade, on the sell edge. - Code Blueprint:
def maxProfit(prices: list[int], fee: int) -> int: hold, cash = -prices[0], 0 # best profit while holding a share / holding none for p in prices[1:]: hold, cash = max(hold, cash - p), max(cash, hold + p - fee) return cash 🌳 Evaluating Subproblems, State Transitions & Space Optimization Invariants
Refactoring and optimizing dynamic programming solutions requires rigorous adherence to state invariants:
1. The Two-Phase Optimization Process
- Phase 1 (Correctness First): Write out the full 2D or 1D tabulation table. Verify all base cases, transitions, and boundary conditions.
- Phase 2 (Space Optimization): Only after the table is verified correct, compress dimensions if transitions look back only a constant distance. If the problem requires path reconstruction (returning the actual sequence of coins/words), you must preserve the full table.
2. Guarding Negative Indices
- In Python, negative index
dp[-1]is valid syntax that accesses the last element of the list. Always verifyrem - coin >= 0before indexing to prevent silent table corruption.
💡 Staff SWE Architectural Invariant:
Dynamic programming is mathematical induction realized as software. The loop ordering guarantees the inductive hypothesis: when computing state , all required dependencies are already fully computed, immutable, and optimal.
Understanding Invariants: Optimal Substructure & Dependency Order
When I compute dp[i], every smaller state it depends on is already final and correct. The loop order is what guarantees that.
DP transforms exponential recursion into polynomial tabulation by evaluating states in topological dependency order and storing optimal answers in an indexed table.
Iterating backward in 0/1 knapsack prevents an item from being used multiple times in the same pass.
Without grounding base cases, recurrence transitions cannot propagate correct values to target states.
Common Questions
"Are top-down (memoized recursion) and bottom-up (tabulation) actually different algorithms, or is it just two names for the same thing?"
They're the same recurrence, the same state, and the same transition — the only thing that differs is how the dependency order gets guaranteed.
Bottom-up commits to an explicit fill order up front (usually smallest state to largest) and trusts that order to guarantee every
dp[i - something]you read has already been written. You, the author, are responsible for proving that order is correct before you write the loop.Top-down writes the recurrence exactly as you'd state it in English — "the answer for
nneeds the answer forn-1andn-2" — as a plain recursive function, with a cache (@lru_cacheor amemodict) added so the same state is never recomputed. The dependency order takes care of itself: the call stack naturally computes whatever a state depends on before that state can return, because it can't return until its recursive calls do. You never have to reason about fill order at all — recursion does it for you.That's why converting between them on request is a strong signal in an interview: if you can write one, you already know the state, the transition, and the base case, which is the entire content of the algorithm — the loop-vs-recursion shell around it is just implementation. Top-down is usually easier to derive first, because you think in terms of the recurrence, not the order. Bottom-up is usually easier to optimize for space afterward (e.g. collapsing a full table to two rolling variables), because the explicit fill order makes it obvious which past states you can safely discard.
Coach discussion points
- 1.
"Why not just take the biggest coin that fits each time? Give me an input where that loses." —
coins = [1, 3, 4], amount = 6. Tests whether the student knows why they are doing DP or is pattern-matching on the word "minimum". The highest-signal opener in this pattern. - 2.
"Say your
dp[i]out loud as an English sentence." — A student who cannot finish the sentence has not defined the state, and every bug after that traces back to it. Do this before looking at any code. - 3.
"Your table has 12 cells and you only ever read two of them at a time. What could you delete?" — Leads to the rolling-variable optimisation by discovery. Follow-up: "and when would that optimisation cost you something you need?" (Reconstruction.)
- 4.
"What is the same about your solution and the naive recursion, and what is different?" — The recurrence is identical; only the caching differs. A student who sees this can convert freely between top-down and bottom-up, which is what the interviewer will ask for next.
- 5.
"Your Wildcard Matching solution passes. Now swap
'*'for regex semantics -- what breaks?" — Tests whether the student understands that regex's'*'is bonded to the preceding element, not a free-standing wildcard. A student who just changes'?'to'.'and keeps the same'*'transition will fail immediately on"aa"matching"a*". - 6.
"Walk me through why
dp[0][j] = dp[0][j-2]in regex butdp[0][j] = dp[0][j-1]in wildcard." — Forces the student to articulate the element-pairing invariant out loud: regex's'*'always consumes 2 pattern positions (the element plus the star) when skipped, while wildcard's'*'is its own standalone unit consuming 1.
Complexity analysis
Coin Change — Time O(amount × len(coins)), Space O(amount).
The outer loop runs amount times; the inner loop tries every coin at each step. With amount ≤ 104 and ≤ 12 coins, that is at most 120,000 operations. Compare with the naive recursion, which explores every combination and is exponential — roughly O(len(coins)^amount). DP is what turns exponential into a product of two small numbers, and being able to state both bounds is the point of the question.
House Robber — Time O(n), Space O(1) after the rolling-variable optimisation (O(n) before it). One pass, constant work per house.
LCS — Time O(m × n), Space O(m × n), reducible to O(min(m, n)) by keeping only the previous row. Note the space reduction costs you the ability to reconstruct the actual subsequence afterwards — you can still get its length. If the interviewer asks for the string itself, you need the full table (or a cleverer method). Say that trade-off out loud; it is a real one.
The general shape: DP cost is (number of states) × (cost of one transition). Say it that way rather than pattern-matching a formula. O(amount × coins), O(n × 1), O(m × n × 1) all fall out of it immediately, and so does any unfamiliar DP problem.
A vending machine must give change for £1.37 using the fewest coins possible. Grabbing the largest coin that fits each time — the greedy instinct — happens to work for British coins, but it fails outright for other coin sets: with coins {1, 3, 4} making 6, greedy takes 4 + 1 + 1 = 3 coins while the true answer is 3 + 3 = 2. The machine cannot rely on the greedy shortcut, so it builds a table of "fewest coins for 1p, for 2p, for 3p…" up to the amount required, each row using the rows below it. Compilers do this for instruction selection, and bioinformatics does it for sequence alignment.
💡 Don't worry if identifying DP states feels challenging right now! Dynamic Programming is simply recursion with memory: caching overlapping subproblems to turn exponential trees into polynomial grids. As you progress through the Archetype Variants (from Climbing Stairs and Coin Change to Longest Increasing Subsequence and Edit Distance), each hands-on challenge will cement this intuition until defining dp[i] state transitions and base cases becomes second nature.
Recomputing overlapping subproblems recursively without memoization: Naive recursion branches exponentially computing
ways(n-1) + ways(n-2). Memoization or bottom-up tabulation reduces this to .Off-by-one on base cases: Reaching step 1 has 1 way; reaching step 2 has 2 ways (
1+1and2). Settingdp[2] = 1offsets all subsequent stairs.Allocating array space when suffices: Storing the entire DP table consumes space. Because step only depends on and , two rolling variables
prev1, prev2suffice.
Staff+ Systems Architecture & Hardware Considerations
Triggers: "maximum profit / minimum cost", "number of distinct ways to reach state", "can reach target boolean", "optimal substructure + overlapping subproblems". Decisions at state depend strictly on optimal solutions to smaller subproblems.
State space dimensionality (1D, 2D, ...). For states with transitions, runtime is . Memory must be managed carefully: transitions depending only on the immediate prior row or step allow rolling array space compression from down to or .
Topological ordering violations (attempting to compute before its dependency subproblems are settled); incorrect base case initialization (e.g. initializing min-cost DP with 0 instead of infinity); off-by-one indices between DP table and 0-indexed input arrays.